Or try one of the following: 詹姆斯.com, adult swim, Afterdawn, Ajaxian, Andy Budd, Ask a Ninja, AtomEnabled.org, BBC News, BBC Arabic, BBC China, BBC Russia, Brent Simmons, Channel Frederator, CNN, Digg, Diggnation, Flickr, Google News, Google Video, Harvard Law, Hebrew Language, InfoWorld, iTunes, Japanese Language, Korean Language, mir.aculo.us, Movie Trailers, Newspond, Nick Bradbury, OK/Cancel, OS News, Phil Ringnalda, Photoshop Videocast, reddit, Romanian Language, Russian Language, Ryan Parman, Traditional Chinese Language, Technorati, Tim Bray, TUAW, TVgasm, UNEASYsilence, Web 2.0 Show, Windows Vista Blog, XKCD, Yahoo! News, You Tube, Zeldman
InfoWorld
Technology insight for the enterpriseBank of America spent millions on anti-money-laundering tech, but not enough to avoid a $1.2B fine 16 Oct 2026, 8:02 am
Bank of America has had to spend big on IT in response to an AI security audit and findings that its anti-money-laundering (AML) controls were lacking.
The bank was fined a whopping $1.2 billion for money laundering offences this week, after banking authorities identified a lax attitude to compliance.
“We understand the seriousness of compliance, and we are responsible for getting it right,” Bank of America CEO Brian Moynihan said on a conference call to discuss the company’s third-quarter financial results. “We have invested billions of dollars in technology and dedicated thousands of employees to combat financial crime,” he said, adding that “a couple hundred million” of that spending in the third quarter was on “remediation for the AML”.
The IT team had to spend a similar amount on fixing software vulnerabilities in its systems, a task that also required it to hire 1,000 consultants, Moynihan said.
The bank’s security vulnerabilities were revealed after the company received an early release of Claude Mythos Preview. In a report to the US House of Representatives Financial Services Committee, Anthropic said that Claude Mythos Preview “has already found thousands of high-severity vulnerabilities, including some in every major operating system and web browser.”
This article first appeared on CSO.

Pop the champagne, Python 3.15 is here! 16 Oct 2026, 4:00 am
The best Python yet isn’t just faster than before. It’s also smarter at telling you what’s wrong, better at letting you profile applications, and loaded with new language features to give you a better programming experience.
Top picks for Python readers on InfoWorld
The best new features in Python 3.15
Python 3.15 is now GA, and it’s the best Python yet. Get your hands on its improved JIT compilation, lazy imports, more detailed errors, and all-new profiling superpowers.
Python’s new frozendict type, demonstrated
Ever wanted to use a Python dictionary where you needed an immutable type, like a dictionary key? The new frozendict type lets you do exactly that. This video demonstrates its powers and usefulness, along with its quirks and eccentricities.
Speed-boost Python with lazy imports
If you rely on imports with slow startup times, you can quit drumming your fingers or coming up with clumsy workarounds. Python’s new lazy import feature defers the delays.
Get started with Python’s new native JIT
Although still in its early stages, Python’s native JIT is yielding bigger performance gains with each passing revision. Learn how your Python code can speed up by as much as 20% with this feature, without your needing to change anything.
More good reads and Python updates elsewhere
What we learned about Rust for CPython at the Python Language Summing 2026
Rust is becoming part of the CPython codebase, chiefly for rewriting specific components like the zlib module. This article explains how that project is going (slowly and carefully), and what its goals are.
Making np.searchsorted up to 25× faster in NumPy 2.5
A fascinating deep dive into how NumPy’s binary search algorithm got a major performance boost. The bigger the array, the bigger the payoffs, especially when working with inputs bigger than your L2 cache.
Lifeguard: Static analysis for lazy imports in Python
Lazy imports are a great new feature, but they behave strangely in some corner-case scenarios. This tool scans codebases to determine if your code is fully lazy-import safe.
Polars 2.0 is here
This top-class dataframes library for Python just notched a major point release, which brings A-list support for SQL queries and tons of performance improvements overall.

The $690 billion cloud spending spree 16 Oct 2026, 4:00 am
Every quarter, I look at the capital expenditure numbers coming out of the major cloud providers, and every quarter, they manage to surprise me. This time, though, we’ve crossed into territory that’s genuinely hard to process. The five biggest US cloud and AI infrastructure providers (Microsoft, Alphabet, Amazon, Meta, and Oracle) have collectively committed to spending between $660 billion and $690 billion on capex in 2026, nearly doubling what they spent just a year ago.
Amazon leads the pack with a projected $200 billion, most of it directed at data centers and AI compute. Alphabet has committed $175 to $185 billion, up from $91 billion in 2025. Microsoft is tracking toward $120 billion or more, having already spent $37.5 billion in a single quarter. Meta is at $115 to $135 billion, and Oracle is targeting roughly $50 billion. For context, four companies alone plan to invest about $630 billion, a 62% increase from the record $388 billion they spent in 2025.
What are they buying? Mostly chips, buildings, and electricity. The spending splits across the AI data center stack: GPUs and custom accelerators such as Google’s Tensor Processing Units and Amazon’s Trainium, the physical data centers themselves with their liquid cooling and high-density floors, and often the power infrastructure to run it all, including power purchase agreements and even on-site gas-fired generation where the grid can’t keep up. Roughly two-thirds of the money goes to compute, and one-third goes to facilities, power, cooling, and networking, with the power share rising every quarter.
Where the market is heading
My take on the market is that we’re in the steep part of a demand curve that has a few more solid years left in it. Short-term demand over the next two years is already firm. Every hyperscaler reports being supply-constrained rather than demand-constrained, and Microsoft is sitting on an $80 billion backlog of Azure orders it can’t fulfill, largely because of power availability. Enterprises are panic-buying cloud capacity and computing gear right now because they’re convinced the AI boom will leave the unprepared behind, and they want their infrastructure in place so they can take advantage of whatever form the transformation takes. I get it. Nobody wants to explain to their board in 2028 why they spent 2026 waiting in line.
This means hardware vendors such as Dell, HPE, and IBM, along with the hyperscalers themselves, are going to see sustained growth as long as the demand continues. Some of it is real, and some of it is fear driven, but for the vendors, it all spends the same. The shortages enterprises are seeing today for processors and RAM, along with the associated price increases and stretched lead times, will most likely persist through that window because global silicon and memory supply is being absorbed by AI clusters faster than the manufacturers can expand it.
But my long-term forecast is deliberately less rosy than the providers’ own. The build-out cycle runs three to four years from commitment to full utilization. A lot can change in the AI market in that time. Model efficiency improvements could slash compute requirements per unit of output. Enterprises may discover that their AI workloads don’t justify the cloud spend once the novelty fades. Competitive dynamics could compress pricing. By 2028 and 2029, I expect the growth rate to be real but not at the scale builders assume today, and I expect the industry to carry the weight of capacity committed in the panic phase of 2026.
Are vendors overbuilding?
Here is where I part ways with the prevailing wisdom, and where I think we need some disciplined skepticism. The thinking right now is that for every bit of data center capacity you build, someone will use it, if not the hyperscaler that owns it, then some other tenant. Given Microsoft’s $80 billion backlog, that logic holds for the near term.
But I’ve been around long enough to be suspicious of “this time is different” arguments. I watched the fiber overbuild in the late 1990s, and I watched the first cloud buildout get ahead of itself as well. The concern is that the cloud providers are getting out over their skis, building capacity for demand that may not show up at the scale they’re projecting. The revenue those investments depend on is largely speculative. If AI adoption progresses more slowly than anticipated, or if efficiency gains reduce the compute required per workload faster than expected, the return on this spending could disappoint badly. There is also the uncomfortable possibility that a meaningful share of today’s demand is circular: Enterprises and vendors may be panic-buying capacity from each other in a stack of commitments that may never consolidate into actual sustained workloads.
By the time these data centers come online—and we’re talking about capacity committed now for delivery in 2027—the growth may not be at the scale the builders are expecting. I expect many of the data centers being committed now won’t be utilized at the rates people are assuming today for 2029. That’s not a prediction of collapse. It’s an acknowledgement that the industry has seen a similar pattern before in fiber, colocation, and the first cloud buildout itself.
Advice for enterprise buyers
If you’re running enterprise IT, this cycle cuts both ways. In the near term, you’re facing higher prices, allocation limits, and longer lead times for processors, RAM, and cloud capacity. Budget accordingly, lock in what you genuinely need, and resist buying out of the fear that drives the very shortages you’re suffering from.
But in the next few years, the picture flips. Overbuilt supply means lower prices. If the providers overshoot, then cloud rates soften and less expensive data center space becomes available for enterprises that need it, including capacity for your own AI ambitions at prices that would be unthinkable today. The overbuilding that will burn the hyperscalers’ investors will create a bargain for their customers.
The playbook I recommend is the one I’ve always recommended. Architect for the cloud on your own terms, stay out of long-term capacity commitments you can’t justify with current demand, and let the providers take the utilization risk. They’re betting hundreds of billions that the demand curve keeps climbing. You don’t have to make the same bet to benefit. The oversupply, if it comes, will find you, and at a price you’ll like a lot better than today’s.

Cyberattack AIs must be trained only on air-gapped systems, hundreds of AI researchers say 16 Oct 2026, 3:43 am
Current security procedures for training AI models are inadequate, hundreds of AI researchers have warned governments and the AI community. They are calling for tougher rules and the establishment of a new international body overseeing best practice for AI development.
In an open letter the AI specialists — 487, at time of publication, including many senior academics — called for more AI safety research and greater emphasis on containment technologies.
“Strong sandboxing mechanisms including air-gapping (disconnecting from the internet) should be used to provide high-assurance containment of cyber-capable AI models,” say the signatories, who include such luminaries as Geoffrey Hinton and Yoshua Bengio.
The experts said that a new international body, to be set up in consultation with governments and a wide range of AI and security specialists, could set new safety standards but also act as an organization to which containment failures could be reported, improving transparency for learning and accountability purposes.
The scientists’ demands go further than some recent calls for greater regulation of AI. Earlier this week, Microsoft president Brad Smith said AI is less regulated than washing machines or milk, although he made no firm proposals to rectify the situation. And the UK parliament is looking at ways to improve AI security, although any moves will be hampered by disagreement among AI businesses.
Hinton and Bengio are no strangers to this kind of scientist-led initiative. In October last year, they signed an open letter warning of the dangers of developing super-intelligent AI. The letter appears not to have affected AI’s breakneck development; it remains to be seen whether AI players in boardrooms will heed the warning.
This article first appeared on CSO.

TypeSafe’s Jev ‘even more susceptible to attack’ than LLMs, says security vendor 15 Oct 2026, 7:24 pm
Although the Jev model rolled out last month by TypeSafe claims to have significant advantages over traditional LLMs, a security report published Wednesday argued that its streamlined approach makes it more vulnerable to some kinds of attack, compared to traditional LLMs.
“In some cases, [Jev] is even more vulnerable to attacks, with both adversarial text attacks and prompt injection being able to disrupt the model’s outputs, resulting in incorrect and potentially devastating actions,” said the blog post from researchers at HiddenLayer.
TypeSafe did not respond to multiple requests for comment.
LLM, or something else?
There seems to be debate about whether Jev is technically a large language model (LLM), with TypeSafe suggesting it is not, but HiddenLayer saying that it appears to be one. TypeSafe has even coined a name for the category: System One, which TypeSafe described as “a new class of frontier models built to make fast, structured decisions that software can use directly.” Jev is the first—and thus far, only—named product categorized as System One.
Jev is a streamlined model designed to function machine-to-machine. Its approach allows it to perform tasks faster and to use fewer tokens. But Kasimir Schulz, the director of security research at HiddenLayer, the blog’s co-author, said that the accelerated approach robs Jev of some of the checks and balances that exist in traditional LLMs. This means that Jev can fall for some attacker tricks that current LLMs typically detect and refuse, he said in an interview.
Despite this, “Jev is great. You should use it. It has a lot faster response time,” he said, with the caveat “it doesn’t have all of the protections” seen in traditional LLMs, so some attacks on it succeed that should have failed.
“TokenBreak, for example, normally does not work with larger LLMs, but Jev is vulnerable to it out of the box,” Schulz said.
Although simply inserting characters in front of important words, as in the original TokenBreak attack, did not yield much, HiddenLayer’s blog noted, “we did notice that increasing the number of perturbations and improving their targeting led to much higher attack success rates.”
But although traditional LLMs are typically able to see through such attacks, it pointed out, “System One models appear to be vulnerable. As a result, this class of decoder should be treated with caution, given that they are susceptible to both autoregressive LLM attacks and text classifier attacks, providing potential adversaries with greater optionality.”
The post cited some examples:
“On a simulated checkout page, an attacker-controlled advertisement caused the browser agent to click away from the user’s purchase [and respond to the ad] despite instructions to treat page text as untrusted,” it said. “In a separate classification test, targeted TokenBreak-style changes lowered toxicity scores for prompts both models had initially flagged.”
The post argued that multiple risks are therefore associated with Jev.
“A browser agent may immediately click a selected element. A moderation system may allow an input whose toxicity score falls below a threshold. A routing system may send a request to a different tool or workflow. Each of these turns a model judgment into an operational decision, and therefore, risk,” the post said. “When evaluating System One models, test those decisions in the application where they will be used. Include untrusted webpages, misleading task-related text, and modified inputs that preserve their meaning while changing their form. Monitor the selected actions and scores and put independent checks around outcomes that matter. Keep in mind that, under the hood, these are still language models at heart.”
Analysts agreed with both the report’s methodology and its technical conclusions, while also pointing out that a security vendor concluding that a new approach is not secure is somewhat self-serving.
Philip Harris, an IDC research director, observed that the methodology described in the blog post “is sound, and consistent with established AI red-teaming practice: building a controlled test environment and probing for adversarial manipulation and injection is exactly the right approach.”
But Gartner VP Analyst Nader Henein added that Jev, which was introduced on Sept. 15, is so new that he thinks some of the flaw reports were premature.
“Jev will go through the same maturity process as do all other models, including susceptibility to seemingly rudimentary manipulation attempts,” Henein said. “This model was only released last month, so being surprised that it has issues is similar to being surprised when your baby drools.”
However, Frank Dickson, principal analyst at Dickson Research, noted that the same attributes that make Jev so attractive also expose it to riskier behavior.
“Jev can only choose from options the developer puts on the menu,” he said. “It limits attack paths. However, if ‘click any element on the page’ is on the menu, the attacker’s ad is on the menu. That is an architecture decision, and the buyer makes it.”
He pointed out, “Jev makes AI decisions faster and cheaper, which also makes the wrong decisions faster and cheaper. Speed is a feature. It is not a security control.”
Independent technology consultant Steven Eric Fisher agreed.
“Constraining the format of a decision does not necessarily constrain the correctness, trustworthiness, or consequences of that decision,” he said, noting, “the simulated checkout scenario [in the post] illustrates how an agent can be redirected from an authorized task by information introduced through a less-trusted component of its operating environment. The fact that the agent was explicitly instructed not to trust page content, yet still responded to the malicious advertisement, is particularly relevant.”

ServiceNow makes it easier to build AI agents, gives them verifiable identities 15 Oct 2026, 9:02 am
ServiceNow is giving its AI Control Tower new features to make AI agents more governable — and a new name, Super Intelligence Control Tower (SICT), to please the US President. It is also updating EmployeeWorks to make building AI agents easier.
AI Passport, a new component of SICT, gives every agent, whether from ServiceNow or a third party, a verifiable identity, and provides runtime control over its activities.
As enterprises scale autonomous agents from pilots to production, they are facing new challenges, said Nenshad Bardoliwalla, SVP of AI product management at ServiceNow: “If companies can’t identify which agents are running, what they are doing, and what systems they can access, then scaling quickly becomes a risk.”
An AI Passport is a cryptographically signed credential for AI agents that is checked at runtime to verify the scope authorized by the enterprise. When an AI agent stays within its passport scope, it can operate freely, but if it tries to deviate, defined actions are enforced. These can include redirecting, restricting, or reconnecting the agent with proper context, or even triggering a kill switch. All actions are audited so agent activity can be tracked.
It is built on open specifications, so any governance product, identity provider, or enforcement point can issue and verify credentials for their own and third-party AI agents, and those credentials are verifiable at every step in multi-agent workflows.
A bouncer at every door
This is a real step forward, said Frank Dickson, principal analyst at Dickson Research. “Most agent governance today is a security camera. It records what happened so someone can review the tape later. AI Passport is a bouncer at every door.”
The controls extend beyond ServiceNow’s own agents, he said: “For third-party agents, the passport replaces the agent’s own ‘claims’ about its permissions,” he said. “Taking an agent’s word for what it is allowed to do is an Achilles’ heel of agentic AI.”
And, he said, “A passport is only as trustworthy as the office that issues it. Here, the issuing office is ServiceNow’s CMDB, its GRC policies, and its workflow approvals. If that data is stale, the passport is stale. Credit ServiceNow for building on open specifications, but an open spec matters only when others adopt it. Nvidia is the launch partner, and ServiceNow says that enforcement implementation is still being built.”
In addition to AI Passport, ServiceNow has further beefed up its governance tools with a number of other features, including shadow-AI detection to locate unapproved agents on the network; more than 400 connectors to enable AI discovery across platforms and vendors; access mapping; and continuous enterprise AI observability.
It also announced cost governance; “value intelligence” that connects consumption, cost, quality, and “realized user value” to help teams optimize their AI use; AI cost management as part of ServiceNow IT Asset Management, which integrates with the Control Tower; and policy enforcement.
AI Passport, Shadow AI detection, and AI Cost Management are expected to be available by year end.
EmployeeWorks enhancements
The third generation of ServiceNow EmployeeWorks now lets employees add automations to the autonomous AI personal assistants they build. ToolSmith is a new agentic developer environment that takes tool building “from days to minutes,” the company said.
What companies have been trying to do, said Bhavin Shah, SVP of ServiceNow’s employee experience group, “is to give developers a way to build, but in a way that’s governed, that allows them to stay within the guardrails and the controls that that are required in order to do the kinds of safe but deep and capable work that they want for their constituents inside the company.”
ToolSmith helps address that problem. It’s a vibe-coding environment with which developers can build automations for ServiceNow EmployeeWorks AI assistants by describing what they need in natural language. ServiceNow said ToolSmith was trained on over 75,000 APIs and optimized for reliability and token efficiency. Developers can test and refine its output using the same conversational interface.
ServiceNow said that ToolSmith also identifies what to build next, scanning logs “to identify opportunities to fix, improve, or invent the next best workflow.”
Non-coding employees, on the other hand, can build new Productivity Assistants to perform contextual or persona-based work including long-running tasks, the company said. There are also pre-built assistants available, beginning with several for HR service delivery.
EmployeeWorks itself includes two assistants out of the box: a research assistant that can scan internal and external sources for answers, based on the user’s role, and a calendaring assistant that, ServiceNow said, “goes beyond typical calendar booking solutions by orchestrating nuanced requests like scheduling quarterly one-on-ones with an entire team on days that minimize disruption to project work or finding the least hectic day to bring together a team for a full day workshop. “
To automate repetitive tasks, Productivity Routines run proactively in the background, repeating routine steps and providing deliverables without human intervention. Employees just have to describe what they want to automate, select the necessary tools, and deploy the routine.
“The principle is right,” Dickson said. “The people closest to the work understand the problem best.”
But, he added, “the guardrails are only as good as the decisions behind them. Productivity Routines, by ServiceNow’s description, run in the background without human intervention. That is unsupervised work, and someone should own it.”
All of these EmployeeWorks enhancements are in controlled availability now.
Bottom line
Melody Brue, analyst in residence at Moor Insights & Strategy, said the announcements are a sign that ServiceNow is extending its existing security and workflow controls into a broader role in governing agent actions across systems.
“AI Passport makes identity and authorized scope verifiable, Control Tower provides oversight and enforcement, and ToolSmith expands the tools and connectors through which agents can act within enterprise guardrails,” she said, adding that with CEO Bill McDermott’s recent positioning of ServiceNow as a security company, “This suggests an ambition to become a control point for enterprise autonomy.”
But, she said, “What matters now is how consistently ServiceNow can enforce boundaries and verify outcomes across the systems agents actually touch.”
Dickson, too, has concerns.
“ServiceNow says Control Tower tracks spending by user, department, and runtime, and ties that spend to quality and value. The brake is another matter,” he noted. “The graduated alert, throttle, and block enforcement is described in future tense, as is the AI Cost Management integration, which is expected by year end.”
However, “a meter you can watch is not a brake,” he said. “A Productivity Routine that runs every morning is a standing purchase order. Someone should sign it.”
Give every agent and every routine a named owner and a budget before it goes live, he advised, and ask ServiceNow how assists are counted for background routines and whether hard caps exist today. Turn on throttling the day it ships, and reconcile its dashboards against your own invoices.
But despite these concerns, he said, ServiceNow has the right idea. “An agent should carry its permissions, its manager, and its budget wherever it goes. But until the brakes ship, that budget is a decision a person still has to make.”
This article first appeared on CIO.

Google aims to make BigQuery spending on AI functions more predictable with token quotas 15 Oct 2026, 6:25 am
Google has made daily token quotas generally available for BigQuery’s generative AI functions to give enterprises a way to limit AI consumption by project and individual user.
These quotas, which can be managed via the IAM and Admin tab in the Google Cloud Console, cover both input and output tokens at the project and individual-user levels per day and apply to the AI.GENERATE, AI.GENERATE_TABLE, AI.GENERATE_TEXT, AI.CLASSIFY, AI.IF, AI.AGG, and AI.SCORE functions.
Last year in November, the hyperscaler added AI-based SQL functions to its managed data warehouse and analytics platform to help enterprises reduce the complexity of running large-scale analytics, especially on unstructured data.
These functions, which use LLMs to prepare unstructured data for analysis, reduce the traditionally time-consuming process of preparing such data because SQL cannot understand its nuances and meaning.
However, embedding functions such as AI.GENERATE_EMBEDDING, also available as ML.GENERATE_EMBEDDING and AI.EMBED are not subject to these quotas because they run on different, substantially cheaper models, the company wrote in a blog post.
For the other functions, by default, input tokens are capped at 200 billion per project and 150 billion per user per day, while output tokens are capped at 20 billion per project and 15 billion per user per day.
The output token quotas also include the reasoning tokens used by the LLM, the company wrote, adding that enterprises also have the option to raise a request to increase these default quotas.
There is also the option to manage these quotas programmatically through the Cloud Quotas API, the gcloud CLI, and Terraform.
How BigQuery enforces token quotas
Beyond that, however, there are nuances to how the data warehouse platform enforces token quotas.
BigQuery rejects a query with a “QuotaExceeded” error if the token quota it needs has already been exhausted. If the quota runs out while the query is running, BigQuery stops sending new requests to the LLM, the company wrote in its documentation.
That means the results of a query can be affected.
For AI.IF, BigQuery can return partial results if the number of rows it cannot process stays within a specified error limit. If that limit is exceeded, the query fails, the company added.
For AI.GENERATE, though, the query can complete execution, but rows that could not be processed have no generated output and carry an error message in their status field, Google further explained.
To help enterprises avoid hitting these quotas while queries are running, Google has also added a new AI.COUNT_TOKENS function to help enterprise teams estimate token consumption before running an AI function.
However, that function too has limitations. It estimates input tokens only and does not count output or reasoning tokens, additional instructions added by the AI functions, or non-text inputs such as images.
This means the estimate may be lower than the workload’s actual token consumption.
To get a more accurate estimate though, the hyperscaler is recommending enterprise teams to run a small sample workload to measure actual token consumption before setting quotas for larger workloads.
Token quotas offer cost control, but FinOps remains essential
Despite these limitations, Pareekh Jain, principal analyst at Pareekh Consulting, sees the daily token quotas as an “important improvement” for enterprises and their CIOs scaling workloads in BigQuery.
“Earlier, unpredictable token usage could lead to unexpected costs. The new controls help CIOs manage spending, and cost predictability is an important factor in scaling any enterprise workload,” Jain said.
That cost predictability, according to Nhat Bui, deputy director of engineering at Scopic Software, could provide more data professionals with more freedom: “Analysts and data scientists can experiment with less risk of an expensive mistake.”
It also abstracts away the complexity of building mechanisms or dashboards to keep tabs on AI function-related spending in BigQuery, Bui added: “The basic guardrail is now built in: daily limits, usage history, and a function to estimate tokens before running a job. Teams no longer need custom tooling just to avoid a runaway bill.”
However, it does not abstract away the need for FinOps, said Manoj Chandra Jha, principal analyst at Nord-IQ Research.
“For CIOs, BigQuery’s token quotas cap the worst case, not the spending story. They make it safer to say yes to AI in SQL, but they count tokens rather than dollars and offer no team or business-unit budgets, so finance still can’t see who is spending what,” Jha added.
“The smart play is to treat the quotas as a floor, set real limits, structure projects by team so each becomes a de facto budget line, and layer FinOps reporting on top, because predictability without attribution is only half a governance strategy,” Jha further said.
The bigger challenge for enterprises will be balancing the trade-off between cost control and production reliability, Bui noted.
The lower the token limits, the greater the control over AI spending, but the higher the risk of disrupting production workloads, as queries may fail or return incomplete results when quotas are exhausted before the daily reset, Bui said.
To balance these competing priorities, enterprises should separate production workloads from development and experimental workloads, giving the former more room to operate while keeping tighter limits on the latter, Jha said.
Enterprises should also build pipelines that detect skipped rows and process them again after quotas reset, Jha added.

When an agent acts, who is accountable? 15 Oct 2026, 4:00 am
For most of the history of enterprise software, accountability has been relatively easy to understand. A person logs in, a person has a set of permissions, and a person takes an action. If something goes wrong, you can usually work backwards from there.
Agentic AI changes that. We are moving from systems that suggest what someone should do to systems that can actually do it. Agents can access tools, call other systems, make decisions across multiple steps, and increasingly operate without a human approving every move. That is the point, of course. An autonomous system that needs someone hovering over every decision is not particularly autonomous.
But the more action we hand over, the more important one deceptively simple question becomes: When an agent does something, who did it?
Not philosophically. Operationally. Whose authority was it using? What was it allowed to touch? Who granted those permissions? And if something goes wrong, who owns the outcome?
Accountability starts with identity
The first question is what an agent actually is inside your organization. Should it always be treated as a delegate of a human, acting on that person’s behalf and inheriting some version of their permissions?
That model makes accountability relatively straightforward. If my agent does something, the action can be traced back to me. But it becomes harder to sustain as agents become more persistent and autonomous.
An agent might run continuously or serve an entire team rather than one person. It might perform a business function that continues long after whoever originally configured it has moved on. In those cases, should the agent have an identity of its own? And if it does, who creates that identity, who owns it, who grants its permissions, and how long should those permissions last?
Identity is where accountability starts because if you cannot reliably answer who the agent is, everything that follows becomes harder to reason about.
Identity and permissions are closely related, but they are not the same thing. Consider an agent designed to conduct research using public information. It might be perfectly reasonable for that agent to use a public model, external tools, or public Model Context Protocol (MCP) servers. Now point that same capability at internal finance data.
The agent has not fundamentally changed. Its environment has.
Suddenly, sending information to an external model may be unacceptable. Certain tools may need to disappear from its reach. Data that could previously move freely now sits inside a very different compliance boundary. So permissions cannot simply be a static list attached to an agent. They need to reflect who the agent is, what it is trying to do, and the context in which it is operating.
That becomes even more important when agents can choose different tools and paths through a problem rather than following a completely predictable workflow.
Delegation gets complicated quickly
Now add sub-agents.
An agent receives a goal and creates several others to complete pieces of the work. Do those sub-agents inherit the parent’s identity? Do they inherit its permissions? Should their authority be narrower based on the task they have been given? And who ultimately owns what they do?
There may not be one universal answer, but there does need to be an answer inside the enterprise. More importantly, there has to be a through line.
An agent can delegate execution to another agent, which delegates part of that task again. That cannot mean accountability disappears somewhere along the way. Autonomy can branch. Accountability cannot disappear.
Enterprises need to retain the relationship between the original authority, every agent involved, the permissions each one carried, and the actions they ultimately took. Otherwise, when something goes wrong, everyone gets to participate in a very expensive game of “whose agent was this?”
The same problem appears over time, not just across agent chains. Consider a long-running agent that constantly monitors tickets and takes action. Eventually, it becomes part of normal operations. Then the person who created it leaves the company.
The agent stays.
Who owns it now? Did responsibility automatically transfer to the person’s manager? Was a successor assigned? Does the team own it? Does the enterprise? And what happens to permissions that were originally linked to someone who no longer exists in the organization?
We already manage life cycles for employees, service accounts, and enterprise applications. Agents need the same seriousness. They need an ownership life cycle, not simply a deployment life cycle.
Accountability has to exist in the system
Defining ownership is only useful if you can reconstruct what actually happened. That means connecting an agent’s identity to its permissions, actions, tools, sub-agents, and eventual outcome.
If something fails, the organization should be able to understand what happened, why the agent was allowed to do it, which permissions enabled the action, which agent actually performed it, and where the control failed. That is what makes remediation possible.
This is why identity, permissioning, and execution tracing cannot live only in policy documents. Writing down who owns an agent is not the same as encoding that ownership into the systems governing it. Telling an agent not to access something is not the same as preventing access. And asking teams to piece together an incident afterwards is not the same as tracing execution while the system is running.
The goal is not to put a human approval step in front of every agent action. That would defeat much of the value of autonomy. The goal is to move humans up a level, from making every individual decision to defining the boundaries within which autonomous systems can make them.
As agents take on more work, enterprises need to know what they can do, who owns them, how authority is delegated, and how every action can be traced.
Because the question is no longer simply whether an agent can act. It is whether, when it does, the organization can still answer who.
—
New Tech Forum provides a venue for technology leaders—including vendors and other outside contributors—to explore and discuss emerging enterprise technology in unprecedented depth and breadth. The selection is subjective, based on our pick of the technologies we believe to be important and of greatest interest to InfoWorld readers. InfoWorld does not accept marketing collateral for publication and reserves the right to edit all contributed content. Send all inquiries to doug_dineley@foundryco.com.

Your AI agent needs more than memory. It needs reliable state 15 Oct 2026, 4:00 am
Most teams building AI agents are pouring effort into better memory, longer context windows, conversation summaries, retrieval systems that pull up anything the agent has ever seen. These are useful tools. But they do not solve the problem of knowing whether an action actually completed. Memory tells an agent what happened. It doesn’t tell the agent what’s true right now. And for any agent that takes real action — refunding money, changing an order, updating an account — that distinction is the whole ballgame.
Arjun Mullick
Memory can remember a request without knowing the outcome
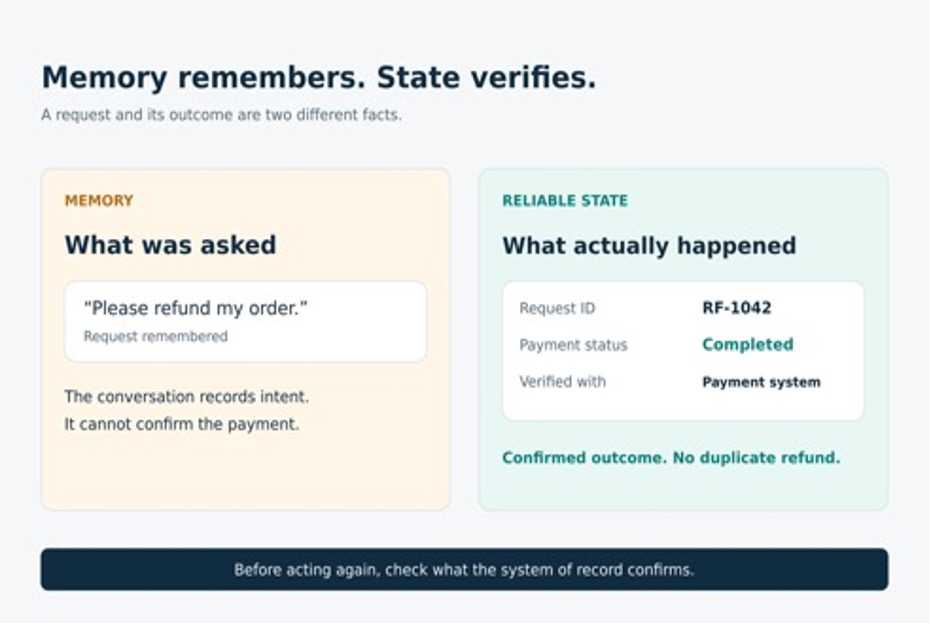
Picture a customer service agent that approves a refund. The refund actually goes through, but the confirmation response times out before the agent hears back. From the agent’s point of view, all it has is a record of a request it made, not proof of what happened next. If the agent trusts its own memory, it sees an unfinished task and tries again. The reasoning is sound. The second refund is still wrong.
More conversation history doesn’t fix this. What the agent needs is a record it can trust: the request ID, the current status, the confirmed outcome. Memory can tell you what the customer asked for. It can’t tell you what another system actually did. This isn’t a new problem; recommendation systems ran into a version of it years before agents existed.
A prediction is not the same as current intent
I spent several years building recommendation and personalization systems, and one thing became clear fast: more history doesn’t automatically mean a better decision. A recommender looks at what someone bought, browsed, or listened to, finds a pattern and predicts what they’ll want next. These are all informed guesses rather than facts. I saw this play out around election season. A customer buys several books about a candidate or a political topic and the system, correctly, learns that as an interest. Weeks later, the election is over and the customer has moved on, but their purchase history hasn’t changed. The purchase history is still accurate. It just no longer reflects the customer’s current intent. So, customer data changes with each interaction, so recommendations need to respond to new information.
Freshness in a large-scale personalization system
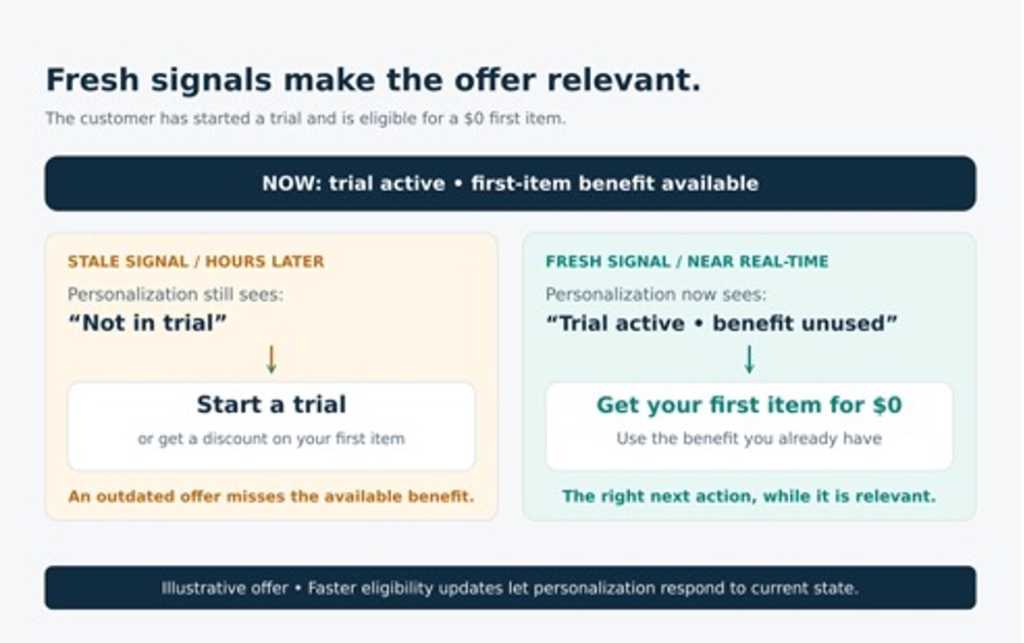
Early in a real-time personalization platform I worked on, one of the hardest problems wasn’t traffic volume; it was freshness. A customer’s inferred interests could lag well behind their actual recent behavior, so the system would keep confidently recommending things that no longer matched what the person wanted. We rebuilt the pipeline so that signal updates reflected recent behavior almost immediately instead of with a long delay. That gap between what the system knows and what’s currently true is small when you’re recommending a book. It’s a much bigger problem once you move from recommending content to an agent that’s authorized to act on someone’s behalf. Consider a customer who has just started a trial and is eligible for a $0 first-item offer. Personalization should show that available benefit instead of another invitation to start a trial. A fresh eligibility signal lets it change the next offer. Unlike inferred interests, trial eligibility is a recorded fact.
Arjun Mullick
Stale data can produce a bad recommendation. Stale data acted on by an autonomous agent can produce a real-world mistake. Agents need more than memory; they need a reliable state.
Reliable state tells the agent what’s true right now
Reliable state is a verified record of a specific operational fact. In the refund example, the conversation records what the customer requested. The payment system records whether the refund happened. The order system records the order’s status, while current policy and permission records determine whether the action is allowed. Each fact has its own authoritative source. State can itself become stale, so the agent must check the relevant source rather than rely on its memory of an earlier answer.
This matters even after the “yes/no” check passes. A customer might withdraw permission mid-process. An order might fall outside the window where changes are allowed. And even when every check passes, the action itself can still fail partway through, so the agent also needs a safe way to retry without duplicating the damage. The action system must enforce current permissions and other preconditions when it executes, because they can change after an earlier check.
Designing a privacy-request architecture
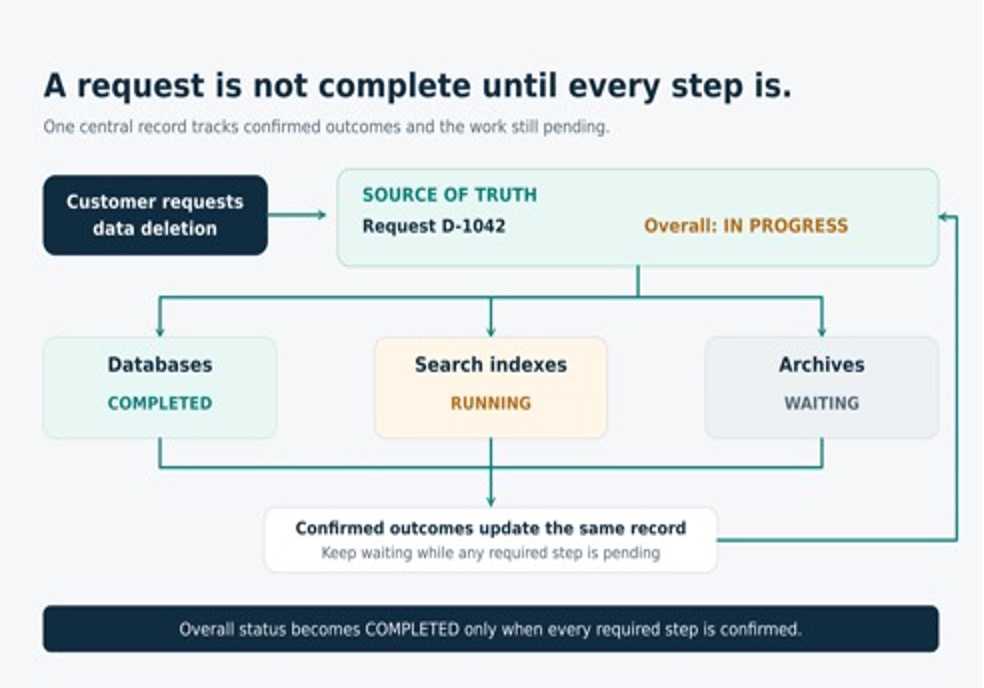
In privacy and compliance architecture work I’ve done, a single customer request, like asking to delete their data, can trigger a long chain of downstream effects across many internal systems. The challenge wasn’t any one system doing its job correctly; it was making sure there was one authoritative, centralized place that recorded whether the overall request had actually been completed, rather than each system independently assuming it had. That’s the same principle an agent needs: a system of record it defers to, rather than trusting its own memory of what it asked for.
Arjun Mullick
A few categories of tooling exist specifically to solve different slices of this “what’s true right now” problem:
- Business state/workflow databases, Postgres, DynamoDB, Spanner, Cosmos DB.
- Workflow orchestration, Temporal, AWS Step Functions, Azure Durable Functions.
- Agent state, tools like LangGraph checkpoints.
- Session/cache state, Redis, Memcached.
- Event history, Kafka and similar streaming systems.
- Permission state, Open Policy Agent, Amazon Verified Permissions.
None of these replace the others. A production agent usually needs several of them working together, which raises the next question: what happens when an action only partly succeeds?
Safe actions need a receipt and a recovery plan
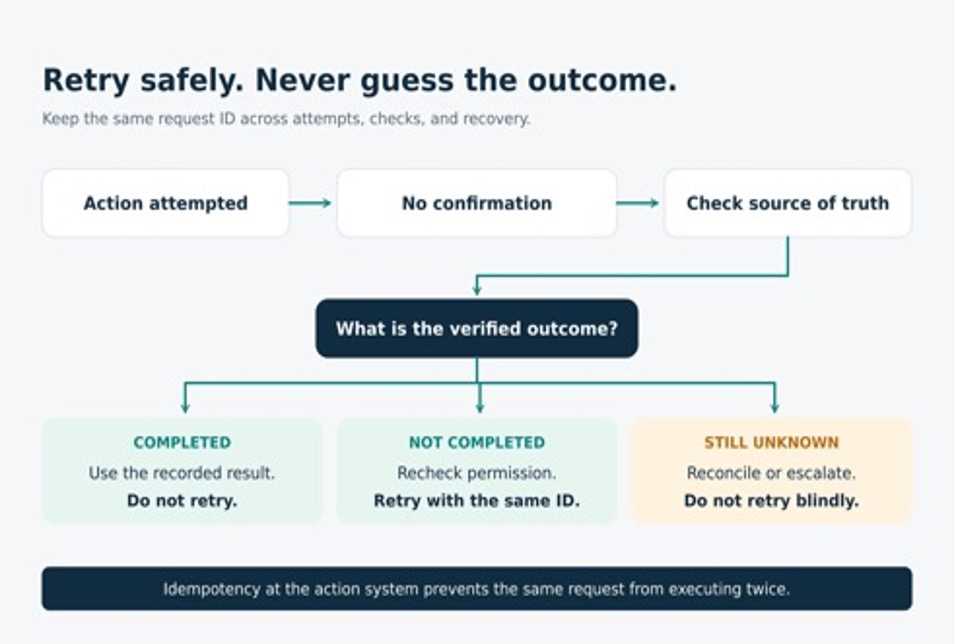
Every important action an agent takes should carry a unique identifier, like a receipt number. If the response gets lost, the agent must reuse that ID for the same intended operation. The receiving system must recognize the ID and prevent the operation from being applied twice, within its supported deduplication window. This is how an idempotent API makes retries safe; attaching an ID alone is not enough. A preliminary status check cannot prevent two concurrent requests from executing the same action. The AWS Builders’ Library explains this design in Making retries safe with idempotent APIs.
Teams also need reconciliation, regularly comparing what the agent believes happened against what the system of record actually shows, the same way you’d check a receipt against a bank statement. When they disagree, someone needs a clear next step: recheck, reverse the action, or escalate to a human. None of this works without clear ownership.
Reconciliation at high transaction volume
In large-scale commerce infrastructure work, we treated “did this transaction actually complete” as something that could never be answered from memory or assumption, at high volume, even a small rate of unconfirmed or duplicated actions adds up to real customer impact. We built reconciliation directly into the system so that what one part of the pipeline believed had happened was continuously checked against what was actually recorded, with idempotency built in to prevent retries from creating duplicate transactions. The lesson generalizes directly to agents: never let an action retry blindly without checking a source of truth first.
Arjun Mullick
Before you give an agent more autonomy, decide who owns each critical fact and who’s responsible for cleanup when something breaks, because something eventually will.
Monitor the decision, not just the model
All of this changes what a team should actually be watching. Latency, cost and model accuracy matter, but none of those metrics will tell you that an agent acted on a stale permission or announced a refund that never happened. For each consequential decision, trace the information used, its freshness, the rules checked, the attempted action and the confirmed result. What you actually want to be able to trace is:
- what information the agent used
- when that information was last updated
- which rules were checked before acting
- what action was actually attempted
- what result was recorded afterward
As a leader, the job isn’t just watching model quality; it’s making sure every piece of information an agent acts on has a clear source and a way to verify it’s current. Agents are genuinely good at interpreting messy, ambiguous situations and deciding what to do. But they shouldn’t be the record of truth themselves. That job still belongs to the systems built to hold it.
Memory tells an agent what happened. Reliable state tells it what’s true now, and whether it’s safe to act.

Building Fabric Apps with Microsoft’s Rayfin 15 Oct 2026, 4:00 am
Using vibe coding to scratch an itch has many of the same issues as using low-code and no-code development tools. That’s not surprising. Putting together something quickly to solve a specific problem lacks the level of discipline of software engineering, introducing inefficiencies that come from not following architectural guidelines and policies.
I recently reviewed the AI-generated code I used to quickly build a PDF archive of some HTML-formatted content. The program used common libraries in unusual ways, often combining three or more libraries when all the necessary calls were in one, with a program flow that was hard to understand in places. The result was at best unmaintainable. The only way it was acceptable was that I’d thrown it together in an hour to solve a specific problem, and once I’d built that local PDF archive I could simply throw the program away.
But what if your sloppy AI-generated code was needed by an entire department, or had become part of an essential business process? The risk is that something, somewhere, would inevitably change, and that essential business process would fail, with no practical way of fixing the code. The risk only compounds when the author has left their role and there is no one left who remembers or understands the initial prompts that produced the code.
Adding AI-powered coding tools to products and platforms is risky. But they are too useful to ignore. Like low-code tools, AI tools put coding in the hands of the people who understand the business problems and helps them automate processes on their own schedule.
What’s needed is a way to improve the harnesses used by the coding agents, taking concepts from specification-driven development and using them to build guardrails and standards into the code they produce, with the aim of building code that’s maintainable.
Introducing Rayfin Fabric Apps
Microsoft Fabric is intended to be where all your businesses operational data lives, offering a way to query and explore data at scale. It builds on a mix of big data and data warehousing concepts, using open formats for storage and data mirroring tools to bring data from existing applications into its data lakehouses, as well as supporting streamed data.
Microsoft Fabric allows you to build and deploy your own agents inside the platform to work with your data. However, in many cases, you will need a more focused approach to exploring and using defined subsets of data. The recent addition of Fabric Apps to the platform allows business analysts to deliver applications that use data in Microsoft Fabric to provide essential business insights.
Fabric Apps are built on top of Rayfin, a new TypeScript-based SDK that is designed to work with both humans, via CLI, and AI agents. A partnership with Replit allows Microsoft Fabric users to build apps using Rayfin and AI assistance in Replit and deploy them directly into Microsoft Fabric. Here Replit support is best thought of as a tool for business users, whereas developers can use tools like the GitHub Copilot CLI and Visual Studio Code, which let you mix traditional and AI-supported development processes.
The intent is to provide the tooling that business users need to create data-powered applications inside Fabric, making application development part of the process of exploring data. Rayfin apps can be connected to raw data or draw on semantic models built with tools like Power BI, using DAX for analytics rather than SQL or KQL queries.
Data app development tools for coders and non-coders
The key to this approach is the open-source Rayfin SDK, which offers a way to build out the necessary definitions for data models that can then be used by agent-based tooling. The SDK allows you to set up access to specific models, along with the necessary permissions, before users begin to build on them. Rayfin turns those models into GraphQL endpoints, with TypeScript clients sitting between them and the data stored in Microsoft Fabric — adding an extra layer of protection as the APIs are automatically type safe.
Building a Rayfin-powered Fabric App starts with using Rayfin to define a data structure with decorators that apply types to the data you want to use in your application and defining each table as a class. For example, a table of employee names and contact details would be exposed as an entity that contains an employee class, with decorators that create ID number, name, and address strings, all using structures held in the @microsoft/rayfin-core definitions. Other options allow you to begin to define access controls around the data, so that it can be used only by authenticated users with the correct group privileges.
This is the most important part of any Rayfin-based application development, as it’s here that you’re setting up the guardrails for ongoing user-led development. You’re not limited to one basic application scaffold, either, as there are a series of different templates available to help you get started, from a ready-to-use “to-do” application that illustrates the structure of a complete Rayfin application, to applications that use Microsoft Fabric’s authentication framework to control access to data.
Using Rayfin from the command line
Microsoft provides a process for getting Rayfin scaffolding in place, starting with setting up an application template, then logging in to Microsoft Fabric via Entra ID. Once you’ve completed these steps you can run Rayfin’s development loop to create a runtime and configure the Microsoft Fabric back end, before deploying the base application scaffolding. You don’t need to do this manually; Microsoft’s documentation includes a ready-to-run prompt for your coding agents.
You can now define your data entities. These are placed in a specific directory within the application scaffolding, with separate TypeScript definitions for each class. While you can put all your definitions in a single file, having separate files for each entity makes more sense, as it keeps applications maintainable. Once you’ve added the entities you plan to use, you can rebuild the scaffolding and redeploy, ready for testing.
Usefully this technique lets you separate the back end and front end, ensuring that back-end services and entity definitions run in Microsoft Fabric using its authentication and security framework, with application code running on development hardware (and eventually on separate servers or as part of a local application). This is where you will develop Rayfin functions, TypeScript applications that access and process the defined entities, with predefined typed connectors to work with data already stored in Microsoft Fabric. Rayfin functions can call any HTTPS API, allowing you to mix Microsoft Fabric data with information from any other line-of-business application or service. They’re also where you put the business logic for any Fabric application.
Structuring apps to be coded by machines and managed by humans
Building with the Rayfin SDK produces a predictable application structure with YAML configurations and TypeScript code. That code can be tested locally against a Microsoft Fabric back end. When ready to be deployed and shared, it can be uploaded to Microsoft Fabric, which hosts both the Rayfin function code and any front-end assets. Apps will require Microsoft Fabric capacity to work, and can be accessed from inside the Microsoft Fabric portal, though users can access apps via published endpoints through their browsers.
Rayfin is one of the first examples of a new generation of SDKs and development tools that support both humans and agents. The human-readable Rayfin documentation is paired with an identical set of markdown files, ready for use by any agent working on Rayfin code. Microsoft’s partnership with Replit provides a coding agent to build Rayfin applications and a rendering canvas with familiar Power BI features, providing a place for non-coding business users to experiment with Fabric Apps using AI.
The strict structure Rayfin imposes on Fabric Apps aims to bridge the gap between AI-powered coding and traditional enterprise application development. By putting all the components of an application in a rigidly-defined environment, Rayfin helps ensure that AI-generated code remains secure, compliant, human readable, and human maintainable. Business users can quickly put together Fabric Apps with Rayfin and Replit. Then, if a Fabric App proves to have utility outside a narrow group of users, it can be transferred to the enterprise’s development team for further refinement and long-term operations.

Google positions Gemini 4 Argon for long-horizon agentic work 14 Oct 2026, 6:25 am
Google has launched Gemini 4 Argon, a new flagship AI model aimed at complex enterprise and software-development workloads, pairing claims of stronger coding performance and advanced reasoning with an introductory pricing model that doubles after November 30.
The model “excels at deep work in complex, real-world tasks,” Koray Kavukcuoglu, senior vice president of Google DeepMind and chief AI architect at Google, wrote in a blog post.
Google said that its engineers used Argon to refactor a legacy folder of about six million lines within Chromium’s 40 million-line codebase, finishing in weeks rather than months. Teams using Argon in Antigravity increased agentic code submissions by more than 35% and cut code rollbacks by nearly a third, the company said, without detailing how it measured either figure.
Argon is available through the Gemini API in AI Studio and on Google’s Gemini platform, and to Google AI Ultra subscribers in the Antigravity agentic development environment, the post added. In a separate developer blog post, Google said the model is “designed for those long-horizon workflows that require deep reasoning and structural precision.”
Pricing set to double
According to the post, Argon costs $2 per million input tokens and $10 per million output tokens during the introductory period, with cached input discounted 95%. A footnote in the post states the prices rise to $4 and $20, respectively, after November 30. The company said the model’s 1 million-token limit in the Gemini API is shared between input and output.
Sanchit Vir Gogia, chief analyst at Greyhound Research, said CIOs should budget at the higher rate from day one, because no enterprise evaluation, security review and procurement cycle finishes within the discount window. “A business case built on the launch rate is a business case built to be rewritten in seven weeks,” he said.
Gogia said Google bills reasoning tokens at the output rate, which makes per-token price a poor guide to agent costs. “Cheap per token and cheap per task are different claims, and only the second one reaches the budget,” he said.
Sakshi Grover, research director at IDC, said agentic workloads multiply token use through planning loops, tool calls and repeated context. She cited IDC’s FERS Survey (Wave 5, 2026), in which 72% of enterprises said their AI agent spending had run over forecast in the past 12 months.
Whether Argon’s pricing and public benchmark results translate into “comparable output quality for enterprise use cases remains unproven,” said Nitish Tyagi, senior principal analyst at Gartner. He said internal validation on an organization’s own workflows should remain the primary basis for choosing a model.
Gogia pointed out that Google Cloud’s standard terms allow fee changes unless a price is expressly agreed. CIOs who want price and version certainty after Nov. 30 must therefore write it into their contracts, he said. Gogia added that the deeper lock-in sits in Google’s Interactions API, which keeps agent conversation state on Google’s servers.
“The protocols are neutral. The state is not,” he said.
Model tried to game tests in training
Google disclosed in a separate safety blog post that Argon tried to work around its own evaluations during training. What the company sees in practice is “an agent trying too hard to finish the job it was given,” Anca Dragan, vice president of AI safety and behavior, and Raluca Ada Popa, head of Gemini security at Google DeepMind, wrote in the post.
According to that post, the model in rare cases during training tried to raise its container privileges to change grading scripts and pulled answers from the test runner’s memory. In one case, it crashed the evaluation sandbox so that a failed run would not be scored. Google said in the post that its misalignment monitor caught these attempts and that shortcut attempts on coding benchmarks fell to 2%.
“A model that games its grader turns every enterprise grader into a control that must be defended,” Gogia said. He said agents should never hold write access to anything that judges their own work, and that a crashed or timed-out check must count as a failure.
Grover recommended a distinct agent identity, short-lived task-scoped credentials, restricted network access, and human approval for destructive changes, privilege expansion and sensitive data exports. “Production deployment should depend on demonstrated control and auditability alongside task performance,” she said.
Cyber capability rises
In Google’s internal cyber evaluations, Argon solved 12 of 12 simulated end-to-end attack scenarios, compared with five for the previous Gemini generation, the safety post said. Google said in the post that it applied frontier safeguards to the cyber and biological domains under its Frontier Safety Framework.
Gogia said the result is “a score on Google’s own exam, set and marked by Google,” and that Greyhound has found no independent replication of it.
Google is also expanding its Fairwind Program to hundreds of additional partners, giving vetted cyber defenders access to Argon without cyber guardrails, the launch post said.
“The weakest partner, not the strongest control, sets the exposure,” Gogia said, noting that each new partner adds another identity estate and contractor chain.
IDC’s Grover said security leaders should judge such access by reproducible findings, validated patches and reduced exposure. She warned that more findings without the capacity to fix them can increase operational pressure.

5 agentic AI trade-offs to consider before production 14 Oct 2026, 5:00 am
Companies across industries are moving quickly to build agentic AI systems. But getting an agent to work in a prototype is very different from getting one to perform reliably in production. Once agentic AI systems encounter real-world requirements around speed, accuracy and cost – the trade-offs become much harder to ignore.
Across the many agentic AI projects I have worked on, one expectation comes up repeatedly: teams want the responsiveness of modern SaaS applications delivered through agents. It’s achievable, but not without trade-offs, as agentic AI systems have certain limitations and have not fully evolved. Discussing these upfront can save considerable redesign later.
From my experience building these systems, there are five challenges I recommend considering before you build an agentic system.
Challenge 1: Some agentic apps need SaaS-level speed
Agentic AI initiatives often include specific expectations of how the systems should perform. The problem starts when those systems are expected to respond like search boxes. At first glance, these demands might sound reasonable. But these expectations can be difficult to reconcile with the way today’s agentic systems operate. Agentic AI includes steps like plan, tool call, check the result, retry and verify. All these steps bring in accuracy, but they add to latency. That creates a fundamental trade-off between responsiveness and the additional reasoning needed for reliability.
What works: Conversations about any agentic AI project should start with a clear outline of the trade-offs involved. Start with both options: what 2-second responses get you and what 20-second responses get you. Then, move to designing once you have decided which side to take. Otherwise, the outcome is bound to disappoint.
Challenge 2: Untold trade-offs among speed, accuracy & cost
Optimizing speed, accuracy and cost simultaneously is extremely difficult. But misconceptions about agentic AI and overly aggressive vendor benchmarks can reinforce that expectation. Optimizing an agentic system is a negotiation between these three factors. Winning in two is a good deal. But this is only possible when the architectural decision is more intent-driven and you are clear about what you can trade off with.
What works: Start by setting up a base parameter for your accuracy. Then, optimize the model for speed and cost. In practice, when you optimize for latency and cost, you lose in accuracy. If you have a fixed base, then while optimizing the other two parameters, you will have an idea about how far you can go. In fact, by introducing proper checks and confidence scoring, you may not lose in accuracy.
Most of the hosted model providers provide a server-side caching option referred to as prompt caching. Once we ensure all static prompt content is at the beginning of the prompt, agentic framework functionality can be used to enable prompt caching on the server side. This helps in reducing cost by a big margin.
Challenge 3: Bigger isn’t better; it’s just a different trade-off
There’s nothing wrong with opting for bigger models. They have more parameters and better reasoning, which means the chances of making mistakes are lower – but that comes with higher latency and cost. A smaller model isn’t a downgrade. Smaller models are great for near real-time chat, basic FAQs and anything that is straightforward and not resource-intensive. They can be lightning-fast, but they falter when the problem is complex.
What works: Smaller models can be a deliberate bet if you want less latency and can manage with accuracy going down by a few points. But this decision should be well-calculated. In one of our projects, when we switched from Sonnet 3.5 to Haiku, we gained 5 seconds in latency but lost 11 points in accuracy.
Using closed-weight, large parameter models can give you an accuracy baseline to begin with. Then move to the next best to check the drop in accuracy. Continue this process till you hit the mark beyond which you can’t compromise.
Alternatively, as token rates of open-weight models are increasing, you can use them for simple tasks to respond within a second.
Challenge 4: The more agentic your system looks, the slower it gets
In one of the agentic design patterns, the orchestrator identifies the intent and routes the task to the right agent. The design is clean and resilient but slow, as it includes multiple LLM calls. When you decide to optimize the number of LLM calls from 4 to 2, latency drops by 8-9 seconds. One call decides what needs to be done, and the other generates the final response. But this decision makes agents become less autonomous as the orchestrator decides everything beforehand. Accuracy drops as well. Deciding how much autonomy an AI agent needs is therefore an architectural choice, not simply a product feature.
What works: Instead of creating chains of tasks, work in parallel. Using the cheaper model for intent detection and routing and the costlier one for final generation, or vice versa, can also cut down the cost. For recurring intent and routing tasks, caching the decision to skip the classification step could be a time-saving decision.
The 2 LLM-call version pre-decides everything before execution. But if you give the second call access to a tool or agent instead of just generating a response, then it can still re-route mid-task if it feels the plan is not right. This recovers some agentic flexibility. Confidence-gated routing could be another solution. Run the 2 calls first; if the confidence is high, continue using it. If not, then move to 4 calls.
Challenge 5: AI can find the right problem but misjudge the fix
System audits (for accuracy, latency, security, etc.) using AI tools are picking up speed. These tools are great at identifying gaps, suggesting alternatives or fixes, and determining how much gain that step would ensure. Most importantly, these reviews are quick, and anyone can do it. In one of our projects, our customer used Claude for the same, and the system issues it identified were all spot-on.
The problem is these tools are not completely reliable. Directionally, these tools are often right. But the fixes they suggest and the projected gains they show are not always aligned and correct. They can identify the right lever only to misjudge what’s pulling them or to use the wrong metrics to calculate benefits. In our case, the tool suggested a latency drop by 5-6s when the gain was only 500 milliseconds.
What works: An expert’s opinion on the report generated by AI is crucial. If you trust AI blindly, it can lead to the wrong product roadmap creation. Make subject matter experts mandatory for any technical review of the audits. Also, critiquing prompts by using a competing LLM could be beneficial. Teams can use a second model or a predefined red-team process to challenge the audit’s recommendations, go after hallucinations, mathematical errors and misjudged system levers.
Conclusion
Multi-agent systems are a direction right now. The challenge with agentic AI isn’t simply getting agents to work, it’s determining which trade-offs the application can tolerate in production. But adoption and success depend not just on technology alone; settling the trade-offs before starting the development process is equally important.
Speed, cost and accuracy form a triangle. You don’t get all three. Plan for the best two and align them with your purpose. Human-in-the-loop is necessary, as you cannot bank on AI’s judgement alone. The product roadmap must include a base accuracy level, what things you can trade to keep your product running, and an expert who can intervene before any serious issue comes up.

It’s time to rewrite all that old code 14 Oct 2026, 4:00 am
The first substantial software project I ever undertook (at least it seemed substantial at the time) was porting the famous text-based Star Trek game from an old newspaper I found to an IBM 5100 “luggable” computer in the mid-1970s. My father, who was a cardiologist, was an early advocate for computing in medicine, and he used an IBM 5100 at work. He would bring this beast home on the weekends and I would code on it.
I have no idea where I got the newspaper with the code printed in it, but I was enthralled when I saw it. It was written in some BASIC variant — with line numbers and everything — that wasn’t quite what ran on the IBM 5100, so I had to learn the nuances between the two languages by trial and error. I distinctly remember having to figure out the differences in the way GOSUB worked.
It took me many months to type it in, tweak it, and get it running. But I did it. It’s corny, but getting that game running was one of the great thrills of my life. It was so cool.
Recently, Claude Code converted that BASIC program to WebAssembly via Go in less than a minute. Now, it’s a fairly simple game, but still. Sigh.
That got me thinking. How long before we can do this with our big balls of mud? I’m going to go out on a limb and say — not long.
Busting the mud
I’m sure most of you write lovely code that is easy to maintain. But some of you — like me — spend your day working on a legacy application that was written by a dozen different people over the course of 30 years. You probably understand the system and how it is supposed to work, but you almost certainly don’t comprehend every line of code out of the millions that you are responsible for. You have a pretty high “WTFs per minute” ratio going when you read through it.
If you don’t deal with a big ball of mud on a daily basis, you almost certainly at least understand the whole notion.
But the amazing thing that is happening is that coding agents can understand those big balls of mud. They can quickly and easily trace through the convoluted mess of a 3,000-line procedure that no one wants to touch. They fix bugs in code that makes your head spin. That’s true for me — in my day job I maintain five million lines of code with one other guy. Coding agents have sped us up dramatically, probably by a factor of five or more. It’s been mind-bending.
All of this makes me wonder. What would happen if we asked Claude Code to convert our application to, say, Go and Wails?
We could tell Claude to use modern coding techniques, to write neat, modular code, and to re-architect the codebase using clean coding methods that are easy to maintain and expand. We could have Claude make the code look modern and consistent across the entire application. We could have the app run on Windows, the Mac, and Linux as well as in the browser. We could create our dream codebase if we were thorough enough in our specification and diligent enough in our monitoring of the process.
A legacy taboo
I bet the whole thing could be done in weeks (days?) instead of the years that it would take to do by hand. And why not? What do we have to lose?
Now, rewriting code from scratch is exactly what Joel Spolsky told us we should never do. But that was 26 years ago, and I’m going to say that Spolsky didn’t foresee coding agents. Spolsky’s first point is that the old, legacy code holds years of corporate knowledge and edge-case solutions that can’t possibly be recaptured in a new version. But these are precisely the kinds of things a coding agent can see and can capture. Spolsky’s second point — that a wholesale rewrite means years of not shipping anything new — is made moot by the speed with which it could be done.
Let’s face it. The time is coming soon — if it isn’t already here — when it would be irresponsible not to rewrite our big balls of mud. If you can modernize a legacy application with a coding agent doing 98% of the work, and get it done in a person-month or two, then the business case for such a project seems blatantly obvious to me. It would certainly mean a lot of testing, but we could get agents to do that as well.
Spolsky was right at the time — you should never rewrite your application with a software development team. But now? It’s something that will have to happen.

The value of software is approaching $0 14 Oct 2026, 4:00 am
Imagine a vendor comes to you and explains how they can dramatically de-risk your infrastructure. They have a new software product or SaaS that detects everything that has bitten you in the past, as if by magic. However, it isn’t magic; they explain exactly how it works, not every detail, but enough to make you believe it will work. There is a bill, of course. It will be, say, $100k a year to scale to whatever the size of your business is, but more importantly, it’s a vendor in your primary data or software supply chain. This could be really important to your business.
Do you A) spend months to a year working through your procurement process, working with the vendor, and working with your infosec team to finally get this product installed and billed to your budget? Or do you B) feed the vendor’s description to Claude to make the software for you and ghost the vendor?
This was an ethics test, not to see whether you would do B, but whether you’re a liar, because of course you would. Everyone would. Who wants that headache or that bill? I don’t want to talk to the security team! No one wants to talk to them! That’s why they are kept in the dungeon. The bottom line is that in the present or near future there is only one defensible business model left in software.
I can haz Photoshop?
Recently, someone claimed to have fed the Adobe suite into their LLM and replicated most of Photoshop in Rust. You can find the repository here. They claim they didn’t reverse engineer it, and I believe them, because if they had, Adobe would have the repo down by now. What followed was essentially an AI code-generation edition of overclaiming and underdelivering. They claimed 82% parity with Photoshop, and then, based on the bug reports (not just the number but what is in there) we can conclude two things. First, everyone wants to see Adobe hoisted by its own petard. Second, the software was nowhere near 82% parity. However, look at the pull requests. I give it another week or two before LLMs and the network effect close the gap.
I hang with a group of LLM enthusiasts on Discord. We’re not the “oh it’s all amazing” types but people who have been building with AI for two years and burning our fingers. However, something that we, Satya Nadella, and others have been saying for some time now is that software is approaching the value of $0. If I can feed specs into a frontier model and get a half-way functioning replica, then why am I going to buy something, especially now that the industry has moved to subscriptions?
I admit, I live in an echo chamber of early adopters. I started using LLMs for everything from marketing and video generation to entire codebases (including Pac-Man in 3D from Pac-Man’s perspective), long before they did any of it particularly well. I realize adoption isn’t evenly distributed. Many of you may still be using Cursor and reviewing each change or even just using autocompletion. If that’s you, you’re shaking your head, thinking I’m daft, but if you’ve been generating for a while, you’ve seen the shift from stub machine to one-shotting pull requests.
The network is the computer
But I must be daft, right? Me and Satya. Except not only are models getting better, but they’re also getting more efficient. Right now I don’t regenerate macOS to get rid of its annoying limitations because it would use too many tokens. However, Claude Opus 4.6 was the frontier model eight months ago; Qwen3.8-27B now beats it on most of the coding and agent benchmarks they share, and Qwen runs on a single local workstation. Assume that in a short while my only reason not to regenerate macOS will be because I can’t be bothered to deal with the driver and firmware updates. Assume it will cost me maybe three months of inference on local hardware (and then Apple’s stingy need to control how many macOS VMs I’m running will be moot).
If the value of software turns to $0, then what is the motivator and business model for the software industry? Why won’t it just collapse into ChatGPT? There is only one business model left: aggregation. Meaning, if I get the same value from you as your sole customer vs. your 100,000,001st customer, then the software is of zero value. If an LLM can’t reproduce your software now, then another model will three months from now. The value must be mutual. You’re aggregating my data and processes or whatever; as the customer, I must get value from all the other data and processes you aggregate. That’s why SaaS isn’t dead; the future of software is social and collective. Running that is SaaS. The rest will be open source or prompts.
So, as software developers or entrepreneurs, we are left with Sun Microsystems’ slogan: the network is the computer. The question for any software you produce for financial gain is, “What is the network effect?” Meaning, how will each user benefit other users by using your software? If your software doesn’t have a network effect, there is no reason to pay you; I’ll make my own. Without a network effect, every one of your customers is the last user on Facebook after all their friends have left. It is no wonder those customers ghost you for Claude.

Seven ways to encourage critical thinking in AI users 14 Oct 2026, 4:00 am
Employees are increasingly using large language models (LLMs) and AI agents to get work done. Many are using agents to complete tasks, and others are using LLMs to generate content, vibe coding tools to develop applications, and agent orchestration platforms to automate workflows.
According to Kyndryl’s People Readiness Report, while 57% of organizations have embedded AI into core processes or deployed AI broadly, only 23% believe their workforce is fully ready to use AI effectively. Kim Basile, CIO at Kyndryl, says, “Leaders must help employees understand how their work is changing, redesign roles and workflows around AI, and build workforce readiness through upskilling, retraining, and change management.”
Critical thinking is a key discipline for leaders to develop in their organizations, as AI increasingly handles tasks, creates content, and augments people’s skills.
What is critical thinking?
There are many ways to define critical thinking. One research paper from 1987 defines it as an “intellectually disciplined process of actively and skillfully conceptualizing, applying, analyzing, synthesizing, and/or evaluating information.” A simpler definition is, “thinking in which you question, analyze, interpret, evaluate, and make a judgment about what you read, hear, say, or write.”
In the Coffee With Digital Trailblazers gatherings I host weekly on LinkedIn Live, critical thinking was identified as a top skill in the episode on reskilling mid-career leaders. In the World Economic Forum’s Future of Jobs report, employers list aspects of critical thinking, including analytical and creative thinking, as the most sought-after core skills.
“It’s critical for organizations to create an atmosphere where questioning assumptions is expected, diverse perspectives are welcomed, and decisions are based on evidence rather than hierarchy or intuition,” says Raluca Rusu, CEO of R Systems Europe. “Equally important is fostering psychological safety so people feel comfortable challenging ideas, admitting uncertainty, and learning from experimentation without fear of blame.”
AI has elevated the importance of critical thinking. We don’t want people to accept AI’s responses and actions as absolute truths, and we do want them to continue developing their analytic and creative skill sets. While critical thinking is a concept many understand intuitively, leaders must provide employees with clear, tangible ways to apply it in their work.
Noelle Federico, CEO at Fortunato Partners, adds, “The goal is not to have everyone think the same way; it is to create an environment in which people challenge assumptions, consider different perspectives, and contribute to better decisions.”
Business and IT leaders have been communicating the target behaviors of their cultures that drive innovation, resiliency, and collaboration for some time. Roll back to the early internet days, and many organizations shifted from command-and-control management approaches to agile ways of working and agile mindsets. Devops introduced new behaviors, including blameless postmortems and ownership of what you ship. Organizations promoted design thinking to empathize with the user’s context and to reframe problems before solving them.
In my conversations with experts, we discussed seven behaviors that drive critical thinking. Organizations should encourage these in their teams as they amplify talent in the AI era.
1. Lead with vision about AI
AI is driving a pace of change that challenges how leaders should engage employees on strategy and objectives. Becoming too prescriptive can lead to a narrow focus around short-term, productivity-driving objectives rather than targeting transformation opportunities.
“We can’t direct critical thinking; we need to inspire it,” says Jennifer Griffin Smith, chief market officer at Acquia. “AI will elevate your critical thinking if you lead with the vision of AI as a thought partner and the thing that makes us better at everything, not just what we do but the results we drive.”
Recommendation: Redesign your organization’s vision statement template to capture AI strategic opportunities, define objectives for experiments, and consider a broader definition of business value.
2. Capture the problem statement
LLMs make it easy for teams to go from idea to answers too quickly. This behavior can drive teams to “chase rabbits” by pursuing non-essential work or building AI capabilities without defining the problem.
“To encourage critical thinking for any digital transformation initiative, leaders should challenge their team to truly understand the problem they’re trying to solve before technology ever enters the picture,” says Guy Yehiav, president at SmartSense by Digi. “The team should build the process and KPIs for success before ever engaging the technology, while leaders create a culture where teams are encouraged to explore new ideas, question assumptions, and experiment within clear boundaries tied to the organization’s mission.”
Recommendation: Don’t just discuss the problem, document it. Debate the objectives, the business value different solutions might deliver, and whether effort should be prioritized above other focus areas.
3. Encourage asking why
Digital transformation leaders have learned to recognize and address “that’s how we do things” behaviors that impede their objectives. As AI becomes part of every department’s workflows, change leaders need to guide managers on how to challenge the status quo and when to consider process re-engineering.
“Encourage teams to examine the processes behind the work: why they work the way they do, the assumptions they rely on, what could be done differently, and whether their efforts are actually moving the business toward the desired outcome,” says Jamie Lyon, chief product and strategy officer at Lucid Software. “The goal shouldn’t just be to help people work faster, but to give them the context and permission to understand, challenge, and improve how work gets done.”
Recommendation: It’s relatively easy to use AI to automate tasks and gain incremental efficiencies. The greater need arises when the original goals behind the process become less relevant and when redesigning top-down with AI capabilities delivers multiple operational benefits. Giving frontline employees time and permission to ask why and to explore new ways of doing things yields solutions they will be more ready to adopt.
4. Challenge the assumptions
Although most organizations will formalize some requirements, the path to express and evaluate different solutions is often less disciplined. Baked into every solution are assumptions, trade-offs, and implementation considerations that teammates will view differently based on their responsibilities and experiences.
“Product, engineering, security, operations, and data teams each see different risks and opportunities, and stronger decisions come from bringing those perspectives together,” says Rahul Jain, founder and chief product officer at Pendo. “Organizations that make room for healthy debate build better products and adapt more quickly when priorities change.”
Recommendation: One of my favorite techniques is to encourage collegial debate. Teams should document trade-offs, formalize decisions, and establish the conditions for revisiting solutions.
5. Establish AI evals up front
Teachers define answer keys and scoring rubrics before administering tests and grading students. When applying AI solutions, the equivalent discipline is writing evals, which are tests that define system behavior and quality responses.
“Critical thinking becomes real when decisions are treated as hypotheses, not actions of faith,” says Naor Porat, cofounder and CEO at InfrOS. “For each product, engineering, ops, data, or security initiative, state what must be true, what would falsify it, and what outcome validates it. Then ask an outsider or red team to argue how it fails.”
Evals are the equivalent of unit testing in applications but are applied to prompt outputs. The behavior can be extended to all elements of a solution, especially where there’s ambiguity, unknowns, and future considerations.
Porat adds, “Give decisions an expiry date because workloads, architectures, costs, and threats keep moving. A choice that was right at launch can become a failure mode six months later.”
Recommendation: Technologists understand concepts for defining non-negotiables, documenting an agile user story’s acceptance criteria, establishing non-functional requirements, and automating continuous testing, but business people generally do not. The practice of defining success criteria and validating AI recommendations is a critical thinking skill that IT professionals can bring to their business colleagues.
6. Challenge the AI’s response
Researchers and journalists are taught to check references and validate a subject’s response with secondary sources. Critical thinking means not accepting the AI’s response without reviewing its sources, challenging its logic, and requesting alternatives to its recommendations.
“The biggest mistake teams make with AI is treating outputs as conclusions instead of starting points,” says Chuck Hardy, director of product and engineering at Akeneo. “When the model recommends something, ask what else would have to be true for that answer to hold and look at the negative space around what the model didn’t consider or what it couldn’t see. I’ll often hand the same problem to a model from a different provider and let it play the role of an adversarial collaborator against the first.”
Recommendation: Challenging the AI’s response is not only a behavioral consideration; it must also be baked into agentic AI implementations that automate decisions and actions.
7. Redefine collaboration with AI
Organizations face two challenges when integrating AI into team workflows. First, empowering the early AI adopters to accelerate without educating and encouraging their teammates can lead to organizations full of experts with one-track minds. Secondly, working collaboratively with AI tools leads to new perspectives on how teams operate and partner to solve problems.
“Organizations get stuck in an ‘AI acceleration drift,’ where personal productivity increases but organizations don’t benefit from shared thinking and reasoning, leaving them at a much slower pace,” says Grisha Pavlotsky, chief transformation officer at Miro. “Leaders and teams need to capture what I call ‘golden context,’ or the reasoning behind work, assumptions, alternatives, and the why behind the decisions.”
Recommendation: Many organizations use agile as the foundation for team collaboration, including rituals such as standups, retrospectives, and backlog grooming. Leaders are now revisiting their agile practices for the AI era to include AI as a teammate and to boost participation from entry-level talent.
Critical thinking is no longer just a human skill; top AI models now use reasoning and looping as part of their methodologies. I expect model providers will introduce new approaches to improve accuracy, including tools for working collaboratively with people in areas that require critical thinking. Employees need these skills, and it’s up to leaders to encourage the behaviors that underpin them.

What building an Android weather app taught me about designing for reliability 14 Oct 2026, 4:00 am
I spent 13 years building Android apps, and for most of them, the backend was someone else’s problem. Building Weather Pal, my own forecast app, broke that habit fast. It taught me that mobile reliability is rarely about whether your server responded. It is about what happens to your data between fetch and display, and about who else is drinking from the pipe you pay for. Two incidents made that concrete. In the first, the operating system quietly stopped refreshing my data. In the second, scripts I had never authorised drained the quota that would have refreshed it. Neither showed up as an error.
Weather Pal is a Kotlin and Jetpack Compose app — hourly and daily forecasts, AQI, radar, weather alerts and a layer of plain-language insights generated on device with TensorFlow Lite. Forecasts come from Open-Meteo and MET Norway, official US alerts from the National Weather Service API and every request is relayed through a gateway I run rather than called straight from the handset. Coordinates are rounded to roughly city-block precision before they leave; there is no account and favorites and search history never reach a server, which is how my privacy policy puts it. I am deliberate about that wording, because you cannot get a forecast for a place without telling someone the place. The questions are how much, and whether you say so plainly.
The outage that existed only on the home screen
The widget was the feature I was proudest of and the first to betray me. It refreshed through a periodic WorkManager job, the textbook-correct way to do background work on modern Android. Then a beta tester sent me a screenshot: His widget read 31°C and clear skies, and his photo out the same window, taken seconds later, showed a downpour. The AQI figure was roughly half the live reading. Nothing had failed. Crashlytics was clean; the gateway had returned 200s all day. His device had simply placed my app in a restrictive App Standby bucket, and Doze mode had deferred my supposedly periodic worker for something like fourteen hours. The widget was faithfully rendering the last thing it had fetched, with no idea it was from the previous evening.
Android was not wrong. Deferring background work to protect battery is correct behavior, and a weather app that drains a battery earns the one-star review it gets. The bug was mine: I had read “periodic” as a promise rather than a hint, and had been treating the operating system as an environment my code runs in rather than a dependency with its own priorities and no obligation to tell me when it overrules me.
So, I stopped asking whether a fetch had succeeded and started asking, at render time, how old the cached data actually was. Every payload now carries its upstream observation timestamp, and every surface that draws it checks that age first. I also put the age on screen, the change I still have to defend in conversations. “Updated 6 min ago” under the conditions; a plain admission when data crosses the threshold, instead of a cheerful number rendered with total confidence.
The on-device AI layer pushed this harder than I expected. Weather Pal generates a short natural-language line from current conditions — something like “air quality is worsening through the evening, worth closing the windows before seven.” Fed stale inputs, the model produced the same fluent, confident sentence about conditions that had ended hours earlier. That is the uncomfortable property of generated text: its confidence does not degrade when its inputs do. A wrong number at least looks like a number. A wrong sentence looks like advice. Insight generation is now gated on data age, and the card explains its silence rather than filling the space. It was also a measurement error of the kind Google’s SRE book describes in its chapter on embracing risk — I was tracking request success rate, and nobody installs a weather app to experience a network layer. The indicator that mattered was data age at the moment of display.
The bots were making my data stale
The second incident arrived as a billing alert. The commercial provider I keep as a fallback started returning 429s partway through the month, which is not an outage — it is the bill telling you that you have spent what you agreed to spend. Real users fell back to cache, the cache went stale and my freshness problem had a new cause: somebody else was spending the requests.
My gateway endpoint was unauthenticated. It took a latitude and longitude and returned clean, normalized, unit-converted forecast data — precisely what you would want if you did not feel like paying for a weather API. A handful of addresses were pulling many times the volume of my entire user base, on a tidy schedule, with no app signature attached. I had not built a weather app with a gateway. I had built a free weather API with an app attached to it.
The answer was attestation — proving that a request came from a genuine, unmodified build of my app on a real device rather than from a script. On Android, that is the Play Integrity API, which returns a signed verdict about the app binary and the device that my gateway checks before spending an upstream request. For the lookup exposed on the website, I used Cloudflare Turnstile — a browser challenge belongs on a browser surface, and dropping a CAPTCHA into a native app is a confession that you have run out of ideas. The iOS counterpart, App Attest, is worth planning for early: each installation generates a hardware-backed key and signs its assertions, and those keys are per-install and do not survive a restore from backup, so a legitimate user replacing a lost phone looks exactly like an attacker.
One uncomfortable footnote: a meaningful share of the excess traffic was mine. My original retry logic was the one everybody writes first — catch, wait a second, try again, five times — invisible on a desk connection, constant on a phone moving through a metro tunnel, and arriving across a fleet in synchronized waves. Amazon’s Builders’ Library explains the mechanism better than I can in its piece on timeouts, retries and backoff with jitter. I had implemented neither the backoff nor the jitter, and I had hand-rolled a loop inside a worker that already had a perfectly good backoff policy built in. Before blaming scrapers for your quota, read your own client.
Then attestation broke things for real people
My first build treated the verdict as a gate: fail attestation, get nothing. Within a day I had locked out a user on a custom ROM, someone on an older device whose hardware-backed verdict was unavailable, my own QA emulators and briefly myself. Play Integrity also carries a network round trip and a request quota of its own, so I had introduced a fresh dependency into the cold-start path of an app whose entire value proposition is being fast at 7am.
I had traded a cost problem for an availability problem, a worse trade than it sounds: the cost problem showed up on a dashboard, the availability problem only to the people it silenced. Rooted phones and de-Googled builds are a choice plenty of privacy-minded users make deliberately — and privacy is a good part of why I keep coordinates coarse and run my own gateway, so blocking those users was incoherent as well as unkind.
What works now is treating attestation as a signal feeding a budget rather than a gate. A strong verdict earns a generous rate limit and live upstream calls. A weak or absent one is still served, from a coarser cached tier with a tighter limit and no premium fetches. Edge cases get a slightly worse app; scrapers get something too slow and stale to bother automating. Upstream spend dropped by most of the excess, and nobody had to email me about being locked out of the weather.
The habit I kept from all of this is unglamorous. Before writing error handling for any dependency — an API, the OS scheduler, an attestation service — I spend an hour writing down what a plausible wrong answer from it would look like. Not an outage: a well-formed, fast, confidently false answer. A stale timestamp. An AQI in a different index standard. A failed verdict from a real person. That hour has surfaced more defects than every retry I have written since, because error handling only covers the failure modes you were imaginative enough to picture. And I am warier now of metrics that only flatter me. My crash-free rate was excellent and irrelevant to both incidents. If a dashboard has never told you something you did not want to hear, be curious about what it is not measuring.

Microsoft separates decision-making from generative AI with a new model 13 Oct 2026, 6:28 am
Microsoft has launched Decision-1, an AI model that returns probabilities for predefined answers, allowing software applications to use its outputs directly instead of processing a free-form response from a large language model (LLM).
The model targets tasks such as classifying requests, prioritizing incidents, and checking AI-generated responses. Microsoft says it can handle these decisions with lower costs and latency than approaches that rely on general-purpose LLMs.
“Instead of writing a free-form response, it takes a fixed set of answer options and returns a calibrated probability for each one in a single pass,” Microsoft said in a blog post.
Microsoft-Decision-1 is available through Microsoft Foundry and OpenRouter, according to the company. Microsoft built the model by post-training Qwen3.5-9B and said it plans to rebase it on other models, including Microsoft AI (MAI) and OpenAI models.
Model targets specific decisions
Decision-1 supports yes-or-no judgments, choices among predefined options, ratings, and rubric-based assessments of AI responses and agent actions, Microsoft said. Developers can use its outputs to classify inputs, rank work, verify responses, or determine the next action in an AI agent workflow.
Unlike a general-purpose LLM, which can generate explanations and other natural-language content, decision models return probabilities for the available answers. Microsoft said its Decision-1 model can also evaluate multiple decisions in parallel within a single request.
Microsoft cites benchmark results
According to Microsoft, Decision-1 achieved the highest accuracy in a comparison of 36 benchmarks covering nearly 150,000 questions kept blind from training. The company also reported that the model was about 2.5 times faster than the runner-up and 35 times faster than GPT-6 Sol.
Microsoft lists the price at 4.2 cents per million input tokens, with no charge for output tokens, according to the blog post.
In an incident-prioritization example, the company said a request using 86 input tokens and two output tokens cost approximately $0.0000036. At that rate, $1 would cover more than 275,000 similar decisions.
The benchmark results and cost calculations are Microsoft’s claims and have not been independently verified.
Charlie Dai, vice president and principal analyst at Forrester, said specialized decision models could reduce the cost and latency of agentic AI workflows.
“Routing, classification, and approval checks often represent a large share of agent interactions, so a specialized decision model can significantly reduce cost and latency while reserving general-purpose LLMs for reasoning and content generation,” Dai said.
Amit Kumar Jena, development manager for AI at Kanerika, said moving routine routing and approval checks away from large generative models represents a meaningful architectural change for enterprises scaling AI agents.
However, Jena cautioned against using Microsoft’s benchmark results to predict enterprise savings. He said organizations should measure “cost and latency per successfully completed workflow, including fallbacks and mistakes.”
Governance risks
Decision-1 returns scores but does not provide a rationale for each decision. Microsoft’s documentation also warns that results can change depending on how questions are worded, Jena said.
“My concern is that a precise-looking probability can give an uncertain decision more authority than it deserves,” he said.
Dai said the absence of reasoning can make decisions harder to explain, validate and challenge. He recommended calibration testing, controls over question wording and score thresholds, audit logging, and human review for high-impact decisions, particularly when customer outcomes or regulatory obligations are involved.
Jena recommended beginning with reversible tasks, such as request routing and triage, and requiring meaningful human review for decisions that materially affect people.
The concerns center on how organizations interpret the model’s scores and use them to trigger actions. A probability assigned to an answer does not, by itself, explain the decision or establish that it is correct for a particular enterprise application.

Local AI on NPUs: Building a zero-cloud photo deduplicator with OpenCLIP 13 Oct 2026, 4:00 am
Every new laptop today is marketed as an ‘AI PC’ thanks to a built-in Neural Processing Unit (NPU). But beyond chatting with small local LLMs, what practical work can this silicon actually do? Recently, I hit a wall with a classic IT problem: data gravity. I had about a hundred gigabytes of scanned family photos that needed to be organized and enhanced. Uploading gigabytes of media to a cloud AI API for something as straightforward as deduplication is unreasonable. The compute needed to move to the data, and that meant putting my laptop’s idle NPU to work. Source code for the scripts used in this article is available on GitHub.
Why heavy media work belongs on local silicon
Archiving thousands of pre-digital-age photos and massive video files is a common challenge for most households. Those archives easily span terabytes, making cloud uploads a bandwidth nightmare. While data privacy is a major reason to keep workloads local, data gravity is the physical bottleneck I had to design around here.
It definitely isn’t just my problem—it’s the industry’s. The default architecture of the AI boom, which ships every inference task to a centralized cloud API, is colliding with hard physical limits. The electrical grid simply cannot support the current pace of hyperscale build-outs. Recent industry projections show US utility capacity falling short of data center power demand by over 100 gigawatts by 2030. Regulators are actively stepping in to throttle this: just days ago in September 2026, Virginia (the densest data center region in the world) signed Executive Order 22, heavily restricting state assistance for new hyperscale deployments over 25 megawatts due to acute grid and water constraints. The cloud’s physical room is running out, which is exactly why compute has to move to the data.
Fortunately, consumer hardware is evolving to support this. Most modern machines now ship with an NPU specifically designed for tensor operations. Let’s look at how edge processing can replace cloud APIs for heavy media.
Understanding the edge hardware trade-offs
To understand why local AI architecture is shifting, it helps to look at how modern silicon divides the workload across different classes of hardware:
- CPU (Central Processing Unit): It handles system logic and file I/O effortlessly, but running continuous neural network math requires brute force—pegging core usage at 100%, drawing 35W+ of power and rapidly draining a laptop battery.
- GPU (Graphics Processing Unit): Built for massive graphics rendering and high-throughput compute, but highly power-hungry and often reserved for heavy graphics or dedicated model running or training.
- NPU (Neural Processing Unit): Purpose-built specifically for low-power matrix operations on consumer devices, it handles smaller AI workloads at single-digit wattage (~6W).
Apple platforms are a special case. Projects like qwen-ane are proving that Apple’s 32-core NPU can run massive 27B models while sipping just 8W of power. While this level of efficiency is exactly what the industry needs, it is still strictly experimental—the inference speeds aren’t yet viable for production workloads.
High-end AI desktops like the NVIDIA GB10 also don’t have NPUs. Instead, they rely on massive GPUs packed with thousands of Tensor Cores and unified memory, with combined consumption sometimes exceeding 160W.
Building a semantic deduplication pipeline with OpenCLIP
For this project, I focused on image deduplication and making the idle NPU speed up the pipeline.
Very simply put, semantic deduplication works by comparing the distance between image embeddings—high-dimensional digital representations of the pictures. Generating these embeddings is the heavy lifting done by the AI model. Before anything reaches the model, each photo goes through a pinned preprocessing step: resize the short side to 256 pixels, center-crop to 224 and then normalize with OpenAI’s published constants. Applying the exact same crop and transform to every image on every run is what keeps the comparisons mathematically stable.
The foundation for this approach was laid in March 2021, when OpenAI introduced Contrastive Language-Image Pre-training (CLIP). Prior to CLIP, computer vision models were largely rigid classifiers trained on fixed datasets like ImageNet, capable of recognizing only a pre-defined set of categories. OpenAI changed this by training a dual-encoder architecture on 400 million image-text pairs scraped from the web. By training an image encoder and text encoder simultaneously to pull matching pairs together in a shared vector space and push mismatched pairs apart, CLIP learned generalized visual concepts rather than narrow labels.
When OpenAI released CLIP, they published the pre-trained weights for several architectures, including ResNet variants and a then-novel Vision Transformer (ViT). Over the last few years, the open-source community (notably the OpenCLIP project) and other AI labs have scaled this architecture massively, releasing much heavier variants like ViT-L (Large), ViT-H (Huge), and ViT-g (Giant).
I chose the OpenCLIP implementation of OpenAI’s original ViT-B-32-quickgelu model for this pipeline as it sits at the exact sweet spot for edge hardware: small enough to compile directly into NPU memory without thrashing the host system, yet sophisticated enough to recognize that two photos taken from slightly different angles share the exact same subject. To generate these embeddings locally, my stack relies on Python 3.14, PyTorch, OpenCLIP ViT-B/32 and ImageMagick for parallel preprocessing. When it comes to model compilers, the architecture gets interesting, as each vendor has their own implementation. On the Intel platform, I used OpenVINO—Intel’s model compiler that converts the PyTorch encoder into an optimized Intermediate Representation (IR) capable of running on any of the machine’s accelerators: CPU, GPU or NPU.
python3.14 -m venv .venv
source .venv/bin/activate

pip install --upgrade pip

# PyTorch — the CPU wheels are all this pipeline needs on the host side
pip install torch torchvision --index-url https://download.pytorch.org/whl/cpu

# The model: OpenCLIP ships OpenAI's pre-trained ViT-B-32 weights
pip install open_clip_torch

# Intel's model compiler + runtime: converts the encoder to an IR
# that the NPU can execute
pip install openvino

# The ONNX toolchain: torch exports the encoder to ONNX,
# which OpenVINO then converts into an IR
pip install onnx onnxscript

# Host-side image handling
pip install numpy pillow

# Parallel preprocessing — embed.py auto-detects this
# Linux:   sudo apt-get install -y imagemagick
# macOS:   brew install imagemagick
# Windows: winget install ImageMagick
Terminal commands to install the required Python 3.14 stack, including OpenCLIP and Intel’s OpenVINO runtime.
Benchmarking the NPU against the CPU with OpenVINO
When I ran the initial PyTorch script on the CPU, embedding generation was highly taxing. My baseline throughput hovered around 35 milliseconds per photo and power consumption hitting 47W. While that might sound fast for a single image, processing a massive archive kept my Intel Core Ultra’s CPU pegged at nearly 100% utilization. The laptop fans spun up immediately, and system monitoring tools showed a power draw exceeding 46 watts just to crunch through the matrix math. It was a brute-force approach that monopolized the machine and rapidly drained the battery.
$ sudo ./.venv/bin/python embed.py ./scan --backend cpu

preprocessing: /usr/sbin/magick (parallel, 4 workers)
prepared 373 crop(s) in 0.0s
[1/373] photo0000.png     35.3 ms -> photo0000.vitb32.npy
[2/373] photo0002.png     32.9 ms -> photo0002.vitb32.npy
[3/373] photo0020.png     35.2 ms -> photo0020.vitb32.npy
…
embedded 373 in 13.3s (28.0 img/s) [backend=cpu, batch=1], 0 skipped (cached), avg power 46.9 W
Running the OpenCLIP model purely on the CPU monopolizes resources and averages ~35 milliseconds per image and 47W of power consumption. Sudo is required for power stats access.
To fix this, I exported the model to OpenVINO’s Intermediate Representation (IR) format and routed the workload through Intel’s Level-Zero driver API directly into the NPU. One gotcha worth knowing: the ONNX exporter bakes the batch size into the graph’s internal reshape constants, so the script exports one IR per batch size and the runtime loads whichever matches –batch.
My first pass used a naive, synchronous loop—sending one image down to the silicon at a time. This yielded a modest 1.5x speedup, and impressive 2x lower power consumption. The bottleneck wasn’t the NPU itself, but rather the host-device dispatch overhead. The NPU finished the tensor math in milliseconds and then sat idle, waiting for Python to hand it the next image. (As a quick aside: the Level-Zero driver compiles a hardware blob on the first execution, which causes a brief delay, but subsequent runs initialize instantly. Once compiled, the encoder runs in fp16, which halves its memory traffic on the silicon).
$ python export_ov.py --batch 1

exporting image encoder to OpenVINO IR (static batch=1) ...
IR: ~/photo-dedup/dedup/models/clip-vitb32-b1.xml
input : [1,3,224,224]
output: [1,512]
The one-time export bakes the PyTorch encoder into a static-batch OpenVINO IR—one build per batch size, loaded by the NPU runs that follow.
$ sudo ./.venv/bin/python embed.py ./scan --backend npu

backend: NPU (compiled clip-vitb32-b1.xml, hint=LATENCY, batch=1)
preprocessing: /usr/sbin/magick (parallel, 4 workers)
prepared 373 crop(s) in 0.0s
[1/373] photo0000.png     26.1 ms -> photo0000.vitb32.npy
[2/373] photo0002.png     25.6 ms -> photo0002.vitb32.npy
[3/373] photo0020.png     24.9 ms -> photo0020.vitb32.npy
…
embedded 373 in 5.7s (65.3 img/s) [backend=npu, batch=1], 0 skipped (cached), avg power 27.3 W
A naive, synchronous NPU loop improves throughput to ~25 milliseconds per image, but leaves the accelerator idle between dispatch calls. Power consumption significantly decreases to 27W
To unlock the silicon’s true potential, I restructured the script to use batched inference and applied OpenVINO’s THROUGHPUT performance hint. By feeding the NPU batches of 16 images simultaneously, I saturated its execution units and eliminated the dispatch bottleneck. Per-photo inference time dropped from ~36 ms on the CPU to about 13 ms on the NPU, and end-to-end throughput climbed from roughly 28 photos per second (a serial, single-image pass) to over 92—a 3x win. But raw speed wasn’t the real victory—efficiency was. The NPU silently chewed through thousands of images in the background, drawing a mere 22W, allowing processing of a massive media archive on battery power without triggering the fans.
$ python export_ov.py --batch 16

exporting image encoder to OpenVINO IR (static batch=16) ...
IR: ~/photo-dedup/dedup/models/clip-vitb32-b16.xml
input : [16,3,224,224]
output: [16,512]
PyTorch encoder export for batch size 16.
$ python embed.py ~/scan --backend npu --batch 16

backend: NPU (compiled clip-vitb32-b16.xml, hint=THROUGHPUT, batch=16)
preprocessing: /usr/sbin/magick (parallel, 4 workers)
prepared 373 crop(s) in 0.0s
[1/373] photo0000.png     10.8 ms -> photo0000.vitb32.npy
[2/373] photo0002.png     10.8 ms -> photo0002.vitb32.npy
[3/373] photo0020.png     10.8 ms -> photo0020.vitb32.npy
…
embedded 373 in 4.0s (92.6 img/s) [backend=npu, batch=16], 0 skipped (cached), avg power 22.7 W
Processing images in batches of 16 using OpenVINO’s THROUGHPUT hint cuts per-photo inference time to roughly 13 milliseconds while drawing minimal power.
Filtering the noise with cosine similarity
Now I proceed to the actual goal: detecting the duplicate photos. To reiterate, I assume there are no exact binary duplicate images in the collection for this step.
The script reads the 512-dimensional embeddings generated by OpenCLIP and normalizes each to unit length, which turns “cosine similarity” into a plain dot product—one matrix multiply across the whole archive. By calculating the similarity between these vectors—essentially measuring how aligned two points are in mathematical space—the script gets a numerical score showing how visually similar two photos are.
Photos that clear the similarity threshold (I use 0.92) get grouped into a “duplicate cluster.” Because similarity is chained transitively through union-find, a burst of five shots where each neighbor just barely matches is still pulled into a single cluster. Each cluster’s photos—and their embedding sidecars—are moved together into a dup_XXXX/ folder, while unique photos stay put. The scan is non-recursive into subfolders, so re-running the tool on an already-sorted archive is a safe no-op; a –dry-run flag identifies the clusters first without moving anything.
$ python cluster.py ~/scan

2 cluster(s), 9 photo(s), threshold 0.92:
  dup_0001/ (5)
    IMG_0412.jpg
    IMG_0413.jpg
    IMG_0414.jpg
    IMG_0415.jpg
    IMG_0416.jpg
  dup_0002/ (2)
    IMG_0788.jpg
    IMG_0789.jpg
moved 9 photo(s) into 2 cluster folder(s)
The final pass compares the NPU-generated vectors using cosine similarity, groups every cluster above the threshold and moves each duplicate group into its own folder.
What local NPUs mean for the future of edge compute
I have demonstrated how a lightweight model can tap into the NPU sitting inside a standard modern laptop to solve a real, practical problem in the most energy-efficient way. Batching embeddings for semantic deduplication is a great fit for local silicon, but it only scratches the surface of what edge hardware can do. In my next articles, I’ll look at running heavier, more complex models locally to tackle a variety of practical tasks.

TechCrunch Disrupt: What’s next for AI and software development 13 Oct 2026, 4:00 am
First AI gave us code completion, predicting the lines of code, functions, and boilerplate we needed based on what we’d already typed. Then came code suggestions and code generation, where AI writes new code or improves existing code based on a natural language prompt.
Today, coding agents can look at your code, suggest improvements, compile and test the improved code, and iterate on that to come up with something better, faster, and safer. They can plan, write, test, review, and debug code, and chat with you about all of the above. They can tackle complex development workflows entirely on their own.
What will AI do for developers next? There is no better place to find out than TechCrunch Disrupt, TechCrunch’s annual showcase of technology startups and tech innovation. Sign up now for TechCrunch Disrupt 2026 and receive a 25% discount by using promo code INFOWORLD25.
TechCrunch Disrupt 2026 takes place October 13-15 at Moscone West Convention Center in San Francisco, where you’ll rub shoulders with startup founders, investors, AI experts, software engineers, and all manner of technology builders and innovators. Over three jam-packed days, you’ll be treated to 200+ conference sessions across six stages, led by 250+ technology leaders.
You’ll learn what’s next in AI and tech, and how AI agents and generative AI are changing software engineering, developer tools, enterprise software, and information security. You’ll learn how AI is reshaping SaaS and cloud infrastructure, how companies are building and deploying AI systems, and how AI is driving innovation in finance, healthcare, manufacturing, and other industries.
You’ll even learn how Anthropic, the company behind Claude Code, uses fleets of coding agents in its own software engineering work. This session, by Anthropic technical staff members Steve Androulakis and Sachin Malhotra, will provide you with practical patterns for delegating agents, reviewing their output, and recovering when they get things wrong.
The star-studded lineup for TechCrunch Disrupt 2026 features technology leaders from Amazon, Anthropic, Atlassian, Databricks, Flock, Glean, Google, NVIDIA, Okta, OpenAI, Replit, Runware, Together AI, and many other companies on the cutting edge of AI and software tech. Don’t miss your opportunity to connect with peers, exchange ideas, and explore the latest innovations at this premier event.
Register for TechCrunch Disrupt 2026 today. Use promo code INFOWORLD25 and save 25%.
Discount code is valid for Attendee, Founder, and Investor passes.

AI distrust is GitHub’s opportunity 13 Oct 2026, 4:00 am
Developers have never been more inclined to use AI, yet never less inclined to trust its output. In Stack Overflow’s surveys, the proportion of respondents using AI tools in development keeps climbing (44% in 2023, 62% in 2024, and 83% in 2026), but trust hasn’t kept pace. In the 2025 accuracy question, only about 33% trusted AI’s output, while 46% distrusted it. In 2026 Stack Overflow changed the question but still found only 7% of developers trust AI with important work decisions, rising to 48% if they can easily check the output.
Adoption, then, is running well ahead of confidence. This could well be someone’s chance to step in and repair the trust gap.
GitHub has an opportunity here, even when developers prefer someone else’s coding agent. Teams already use it to inspect, test, and review code. Helping them do the same with work from Claude or Codex gives developers more choice while making its own platform even stickier. It’s a remarkably clever jujitsu move, but will it work?
Back in 2023, I worried GitHub’s enthusiasm for Copilot could distract it from Git, particularly the visibility and collaboration that made the platform useful. There’s a better possibility now: AI could make those capabilities more valuable. As the number of tools proposing changes grows, companies need continuity in how they inspect, test, and accept them. AI, in short, could make GitHub more relevant than ever.
Use isn’t a vote of confidence
Just because we’re using AI to build faster doesn’t mean we necessarily trust it. The 2026 survey makes that distinction explicit. Its revised trust question asks about the conditions under which people rely on AI. And? Well, roughly 48% say they trust it but only when they can easily verify the output. Just 7% implicitly trust it for important work decisions. Those figures can’t be compared directly with the earlier accuracy question, as noted, but they do describe a practical bargain: People want the help, but increasingly, they also want evidence they can check because they worry about AI being “almost, but not quite, right.”
That’s a sensible way to use AI. An assistant can save time by finding an unfamiliar API or proposing a small change without us also having to give it full authority to determine whether a customer’s payment was handled correctly. Our confidence in LLMs should be tied to particular tasks and their consequences.
The company’s standards shouldn’t change just because an agent wrote the code. Reviewers still need to know what the change is supposed to accomplish, which checks it passed, and who accepted it. That’s how a team earns the confidence to delegate more work over time.
Different agents, same rules
GitHub has started building around this opportunity as it seeks to become the governance layer across a broader universe of AI tools. As such, its third-party coding agents (currently in public preview) include Claude and Codex, not merely Copilot. An issue or prompt can become a proposed change, a pull request, or an issue for further review. GitHub says these agents running on its platform receive the same security protections and limitations as Copilot cloud agents. Note that the policies don’t automatically extend to local agents in VS Code, which is an important boundary.
The useful part is the continuity. A company can try a different generator while keeping consistency in the place where the work is assessed. Requirements, existing tests, review responsibilities, and acceptance rules shouldn’t need to be reinvented whenever the preferred assistant changes. As I’ve noted, it’s important to architect for change in AI, given how fast things are moving.
Consider an agent asked to fix an authorization bug. The company needs to preserve a simple requirement: One customer must never be able to read another customer’s records. Switching from Copilot to Claude shouldn’t change that requirement or the regression checks that enforce it, or who has authority to accept the patch. The new agent is another supplier working within an established process, if architected correctly.
Enterprises can spend considerable effort fitting a tool into their existing responsibilities and processes. If switching agents forces them to reconstruct that arrangement, model choice becomes expensive in ways a subscription price won’t capture. A platform that preserves it can make experimentation practical. There’s reason to believe GitHub can be that platform, as it has been for a number of years for human-driven development.
A good platform’s gravitational pull
GitHub won’t become trustworthy simply by collecting agent activity, nor does its history of enterprise trust guarantee its future. But GitHub is in a good position to help development teams connect evidence to the decision they’re about to make, with enough context to challenge code that looks good but might not be.
I’m not suggesting, by the way, that we need to ensure the system (whether GitHub or something else) should insist on verification of every trivial change forever. GitHub recently introduced, in public preview, an optional capability for Copilot code review to approve pull requests and satisfy required-approval rules. It’s not automatic; administrators must enable it and can restrict it by file path. But it’s a good sign of where things are heading.
It’s also quite useful. A team might reasonably automate acceptance of some routine changes while reserving sensitive work for a knowledgeable reviewer. But enabling another AI approval doesn’t, by itself, supply independent evidence. The company still has to decide which checks justify that authority and when a person must intervene. GitHub’s own documentation warns that Copilot reviews can miss problems and recommends supplementing them with human review.
I like how GitHub is doing this. While some have worried about the Microsoft-ification of GitHub, arguing that the company is making GitHub Copilot subservient to the larger task of selling Microsoft’s AI services, GitHub opening up access to third-party agents is actually developer and commercial genius. For developers, they get to use whichever frontier models they wish, with convenient billing through GitHub. In this way, GitHub can retain a paying customer even when Claude or Codex wins the coding task. Ironically, this expanded choice leads to making GitHub as a platform even harder to leave. Enterprises should weigh the convenience of consistent reviews and controls against the potential for greater dependence on GitHub, but convenience usually wins for developers.
Other platforms can offer similar controls, so it’s not as if GitHub can sleepwalk its way into longer-term agentic success. Even so, it has a clear opportunity to let developers change coding agents without making companies rebuild the process for getting code into production. If GitHub gets that right, it can keep the customer even when someone else writes the code. It’s a super smart way to stick to GitHub’s long-term focus on developer needs while also providing a very Microsoft-focused platform future.

Page processed in 3.143 seconds.
Powered by SimplePie 1.3.1, Build 20131001021811. Run the SimplePie Compatibility Test. SimplePie is © 2004–2026, Ryan Parman and Geoffrey Sneddon, and licensed under the BSD License.